Best Local LLM for Coding with 12 GB VRAM?
By Hans Kuepper · Founder of PromptQuorum · Discovery engine for open-weight & open-source AI
Key Takeaways
- ✓Gemma 4 12B (Google, Apache 2.0): 7.7–8.0 GB download, 256K context, 72.0% LiveCodeBench v6 (vendor-reported) — the top coding pick for any 12 GB GPU
- ✓Qwen2.5-Coder 14B Q4_K_M (~9 GB) is still a solid code-specialised option, but it dates from 2024; newer Qwen coders such as Qwen3.8 27B (18 GB) need more than 12 GB
- ✓Devstral Small 2 (24B, 15 GB) and Qwen3.8 27B (18 GB) only run on 12 GB with CPU offload, which slows generation sharply
- ✓Raise the context window to 8192 or more for coding — the default window truncates real source files — and confirm with ollama ps that the model sits fully on the GPU
Quick Answer
Gemma 4 12B is the best coding model for a 12 GB VRAM GPU: its Ollama download is 7.7–8.0 GB, and Google reports 72.0% on LiveCodeBench v6 for the 12B model. Qwen2.5-Coder 14B (~9 GB) is the code-specialised alternative. Qwen3.8 27B (18 GB) and Devstral Small 2 (15 GB) do not fit in 12 GB.
- ▸Gemma 4 12B: 7.7–8.0 GB download, 256K context, Apache 2.0
- ▸Qwen2.5-Coder 14B Q4_K_M: ~9 GB, code-specialised, supports fill-in-the-middle
- ▸Ornith 9B: 5.6 GB, MIT licence, built for agentic coding
The Coding Pick for 12 GB
Gemma 4 12B is the best coding model for a 12 GB VRAM GPU: the Ollama download is 7.7–8.0 GB, which leaves about 4 GB for the KV cache, and Google reports 72.0% on LiveCodeBench v6 and a Codeforces Elo of 1659 for the 12B model. It is licensed under Apache 2.0, supports a 256K context window and accepts image input, so you can paste a screenshot of an error or a UI bug. These benchmark figures are vendor-reported; we did not run our own.
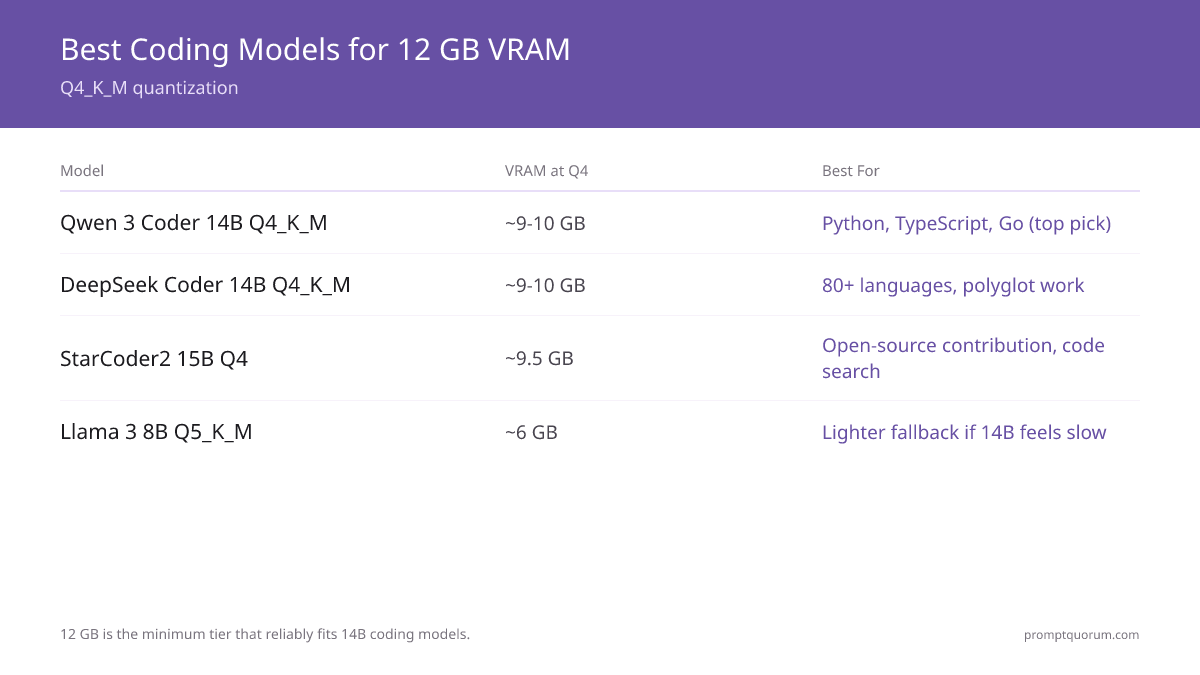
Qwen2.5-Coder 14B Q4_K_M (~9 GB) still fits and remains the code-specialised choice with fill-in-the-middle support, but it is a 2024 model. Ornith 9B (5.6 GB, MIT licence) targets agentic coding and leaves the most headroom for long context. Devstral Small 2 (24B, 15 GB) and Qwen3.8 27B (18 GB) exceed 12 GB and only run with CPU offload.
If you are on an 8 GB card instead, see the best LLMs for AMD 5700X + RTX 3070 Ti for the 8 GB compromise options.
| Model | Download size | Best for |
|---|---|---|
| Gemma 4 12B | 7.7–8.0 GB | Top pick: coding, images, 256K context |
| Qwen2.5-Coder 14B Q4_K_M | ~9 GB | Code-specialised, fill-in-the-middle |
| Ornith 9B | 5.6 GB | Agentic coding with long-context headroom |
| Devstral Small 2 24B | 15 GB | Does not fit; needs CPU offload |
| Qwen3.8 27B | 18 GB | Does not fit; needs 18 GB+ memory |
Settings That Matter for Coding
Set the context window to at least 8k for coding work — a short default window truncates source files of a few hundred lines. Gemma 4 12B's ~8 GB of weights leave roughly 4 GB of a 12 GB card for the KV cache and runtime; Qwen2.5-Coder 14B at ~9 GB leaves less, so keep its context moderate. Set it with OLLAMA_CONTEXT_LENGTH=8192 before starting the server, or /set parameter num_ctx 8192 inside ollama run, then run ollama ps to confirm the model is on the GPU and not split with the CPU.
Enable Flash Attention (OLLAMA_FLASH_ATTENTION=1) and, if you need more context, set OLLAMA_KV_CACHE_TYPE=q8_0, which roughly halves KV-cache memory compared with the default f16 cache at a small quality cost. The environment variables can be combined in one launch.
For the full ranking beyond 12 GB, see the best local LLMs for coding guide.
ollama pull gemma4:12b
ollama run gemma4:12b

# code-specialised alternative
ollama pull qwen2.5-coder:14b-instruct-q4_K_MRelated Guides
- ▸Best Local LLMs for Coding -- full ranking beyond 12 GB
- ▸Best MoE Models for Local Coding -- MoE coding models
- ▸Continue.dev Acquired by Cursor: Shutdown and Alternatives -- coding tool comparison
Quick Answers About Coding LLMs for 12 GB VRAM
What is the best coding model for 12 GB VRAM?▾
What is the best local LLM for 12 GB VRAM in general?▾
Do Qwen3.8 27B and Devstral Small 2 fit in 12 GB of VRAM?▾
Should I use Q4_K_M or a higher quantization on 12 GB?▾
Can I use fill-in-the-middle (FIM) autocomplete with these models on Ollama?▾
suffix field of /api/generate for models whose template supports it. Check each model's Ollama page for insert support before wiring it into an editor; for autocomplete, Qwen2.5-Coder is the safer choice.Want the full breakdown?
Read the complete guide →