Mistral Small 24B vs Qwen3 14B vs Llama 3.1 8B: Which to Run Locally?
Quick Answer
Pick by VRAM: Llama 3.1 8B (4.9 GB), Qwen3 14B (9.3 GB), Mistral Small 3.1 24B (14.4 GB). Qwen 14B wins at 12 GB VRAM. Mistral Small 24B wins above 16 GB on reasoning tasks.
- ▸Llama 3.1 8B Q4_K_M: 4.9 GB VRAM, ~45 tok/s on RTX 4090, MMLU 66.6% — best for 6–8 GB cards
- ▸Qwen3 14B Q4_K_M: 9.3 GB VRAM, ~28 tok/s, MMLU 74.8% — sweet spot for 12 GB cards
- ▸Mistral Small 3.1 24B Q4_K_M: 14.4 GB VRAM, ~20 tok/s, MMLU ~81% — only for 16 GB+ cards
Key Takeaways
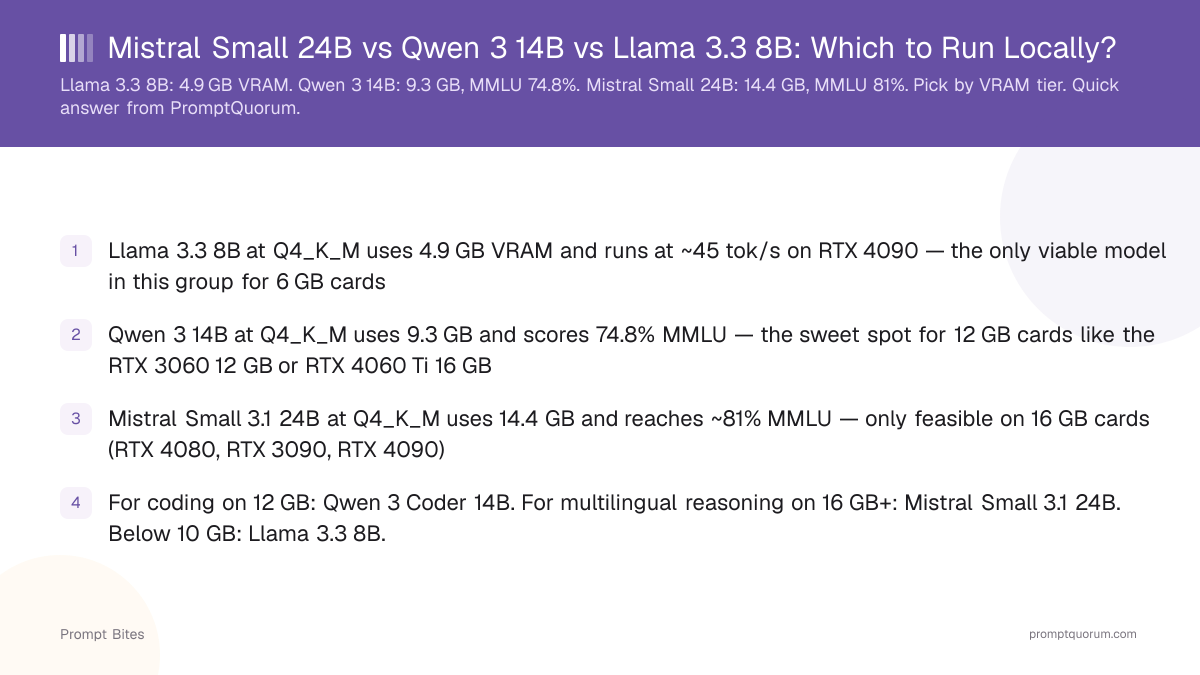
- ✓Llama 3.1 8B at Q4_K_M uses 4.9 GB VRAM and runs at ~45 tok/s on RTX 4090 — the only viable model in this group for 6 GB cards
- ✓Qwen3 14B at Q4_K_M uses 9.3 GB and scores 74.8% MMLU — the sweet spot for 12 GB cards like the RTX 3060 12 GB or RTX 4060 Ti 16 GB
- ✓Mistral Small 3.1 24B at Q4_K_M uses 14.4 GB and reaches ~81% MMLU — only feasible on 16 GB cards (RTX 4080, RTX 3090, RTX 4090)
- ✓For coding on 12 GB: Qwen2.5-Coder 14B. For multilingual reasoning on 16 GB+: Mistral Small 3.1 24B. Below 10 GB: Llama 3.1 8B.
VRAM Requirements: Which Card Runs Which Model
The choice between these three models is primarily a VRAM decision. At Q4_K_M quantization: Llama 3.1 8B uses 4.9 GB, Qwen3 14B uses 9.3 GB, and Mistral Small 3.1 24B uses 14.4 GB. This maps directly onto three GPU tiers: 6–8 GB cards (Llama 3.1 8B only), 10–12 GB cards (Qwen3 14B), and 16+ GB cards (Mistral Small 24B).
Speed on RTX 4090 at Q4_K_M: Llama 3.1 8B runs at approximately 45 tok/s, Qwen3 14B at ~28 tok/s, and Mistral Small 3.1 24B at ~20 tok/s. On an RTX 3060 12 GB, only Llama 3.1 8B and Qwen3 14B fit — Mistral Small 24B requires at minimum a 16 GB card to avoid spilling to CPU RAM.
The benchmark spread is meaningful: Mistral Small 24B's 81% MMLU is 14 points above Llama 3.1 8B and 6 points above Qwen3 14B. On complex multi-step reasoning and instruction-following tasks, this gap is noticeable in practice.
| Model | VRAM (Q4_K_M) | Speed (RTX 4090) | MMLU | Minimum GPU |
|---|---|---|---|---|
| Llama 3.1 8B | 4.9 GB | ~45 tok/s | 66.6% | RTX 3060 6 GB |
| Qwen3 14B | 9.3 GB | ~28 tok/s | 74.8% | RTX 3060 12 GB |
| Mistral Small 3.1 24B | 14.4 GB | ~20 tok/s | ~81% | RTX 4080 16 GB |
Quality vs VRAM: When Each Model Wins
Llama 3.1 8B wins on VRAM efficiency. At 4.9 GB Q4_K_M it is the only model in this group that fits a 6 GB card with headroom for a 4k token context window. It scores 66.6% on MMLU and delivers snappy interactive responses (~45 tok/s on RTX 4090). For chat, quick coding queries, and daily use on constrained hardware, it is the correct pick.
Qwen3 14B wins at 12 GB VRAM. Its 74.8% MMLU places it well above Llama 3.1 8B on reasoning and coding — and it fits within the most common prosumer GPU tier. The Qwen Coder 14B variant (same size, code-tuned) scores approximately 78% on HumanEval. If your primary use is coding and you have a 12 GB card, Qwen3 14B is the answer.
Mistral Small 3.1 24B wins on quality when VRAM allows. Its 81% MMLU and strong multilingual performance make it the top choice for 16 GB cards. It handles long-form reasoning, structured output tasks, and complex instruction sets more reliably than the 14B-class models. On an RTX 4090 24 GB it fits at Q5_K_M for even better quality.
For a direct 14B-class comparison see the Qwen 14B vs Llama 8B comparison, which includes coding benchmark detail.
Quick Answers: Mistral Small 24B vs Qwen 14B vs Llama 8B
Can Mistral Small 24B run on an RTX 3060 12 GB?▾
Is Mistral Small 24B better than Qwen3 14B for coding?▾
Which model should I use on a 16 GB GPU like the RTX 4080?▾
How does Llama 3.1 8B compare to Llama 3.2?▾
Want the full breakdown?
Read the complete guide →Related Prompt Bites