No Single "Best" AI Model — Choose by Task
📍 In One Sentence
Frontier models now differ less in raw capability than in where they are strongest, so the useful question is which model fits the task rather than which model ranks highest overall.
💬 In Plain Terms
Asking which model is best is like asking which vehicle is best. The honest answer is what are you carrying and how far. Benchmarks describe an average; your work is a specific job, and the leaderboard cannot see it.
No single AI model is best for every task. GPT-6 Astra is a strong fit for tool integration and reasoning; Claude Opus 5.5 is often favored for writing and code quality; Gemini 4 Argon pairs a 1M-token context window with deep Google Workspace integration; DeepSeek and Baidu ERNIE are essential for mainland China workloads.
When you have a new task, the first question should not be "what is the best model?" but rather "which model is best for THIS task, in THIS geography, at THIS budget?" Benchmarks and leaderboards shift every few months. Your actual task — your specific writing style, codebase, customers in China, data sensitivity — should drive the choice.
PromptQuorum is a multi-model AI dispatch tool that solves this directly: send one structured prompt to GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, DeepSeek, Baidu ERNIE, and local LLMs (Ollama, LM Studio) simultaneously. See all responses side-by-side. Let PromptQuorum score which model performs best for YOUR task, YOUR data, YOUR brand voice — not YouTube benchmarks.
Quick Decision Matrix — Pick Your Starting Model
Choose your starting model based on your primary task. Most teams use multiple models — start with the right one and switch as needed.
- GPT-6 Astra wins: multi-agent workflows, tool integration, API ecosystem, multimodal (images/audio). Start here if integrations matter.
- Claude Opus 5.5 wins: writing quality, code review, reasoning depth, enterprise safety. Start here for content/code quality.
- Gemini 4 Argon wins: long documents (1M tokens), batch processing, Google Workspace. Start here for large-scale document analysis.
- DeepSeek/Baidu ERNIE wins: mainland China (required for latency/access), high-volume cost-sensitive tasks. Only choice if data stays in China.
- Use PromptQuorum to test all 5 on your actual task — benchmarks lie; your data tells the truth.
Your Priority | Start With | Why | When to Switch |
|---|---|---|---|
| Complex writing & analysis | Claude Opus 5.5 | Highest output quality; cuts revision rounds | Switch to GPT-6 Astra if you need multi-tool workflows or integrations |
| Coding & development speed | Gemini 4 Argon or Flash | 1M context (load entire projects); low intro price | Switch to Claude for deep debugging or code review; GPT for tool integration |
| Multi-agent workflows / APIs | GPT-6 Astra | Richest third-party ecosystem; best tool calling | Switch to Gemini to save costs on high-volume tasks |
| Mainland China users/data | DeepSeek-V4 or Baidu ERNIE | Only practical choice — Western models restricted/slow | N/A — compliance/latency requirements make switch impossible |
Quick Facts
At a glance — key figures before you dive in:
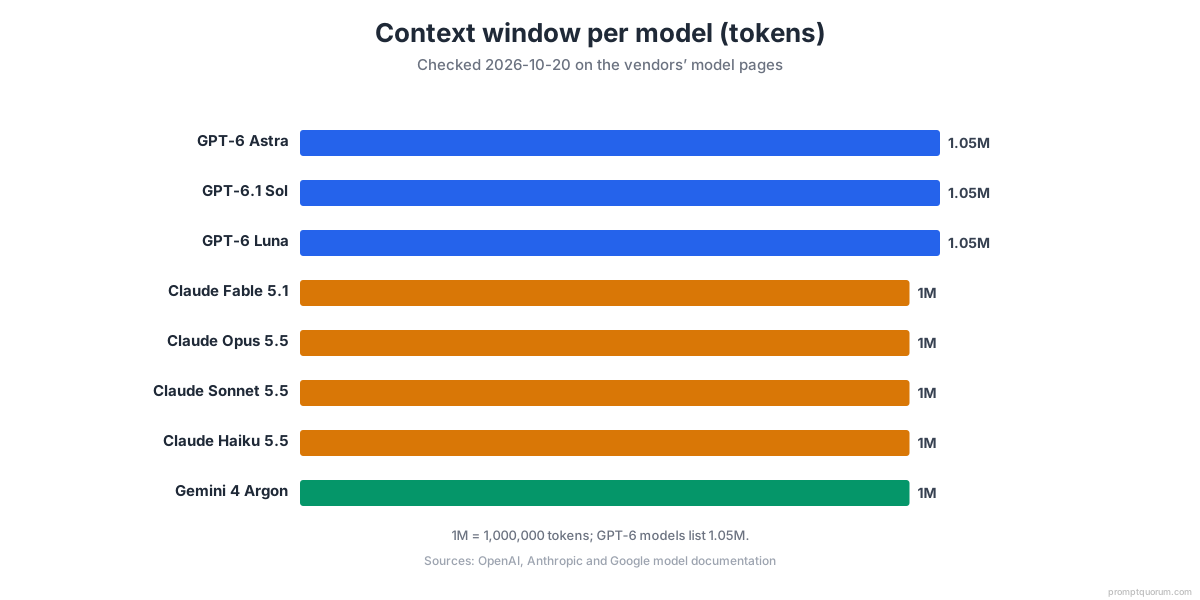
- Context windows: GPT-6 Astra (about 1.05M), Claude Opus 5.5 (1M), Gemini 4 Argon (1M) — all three roughly equal
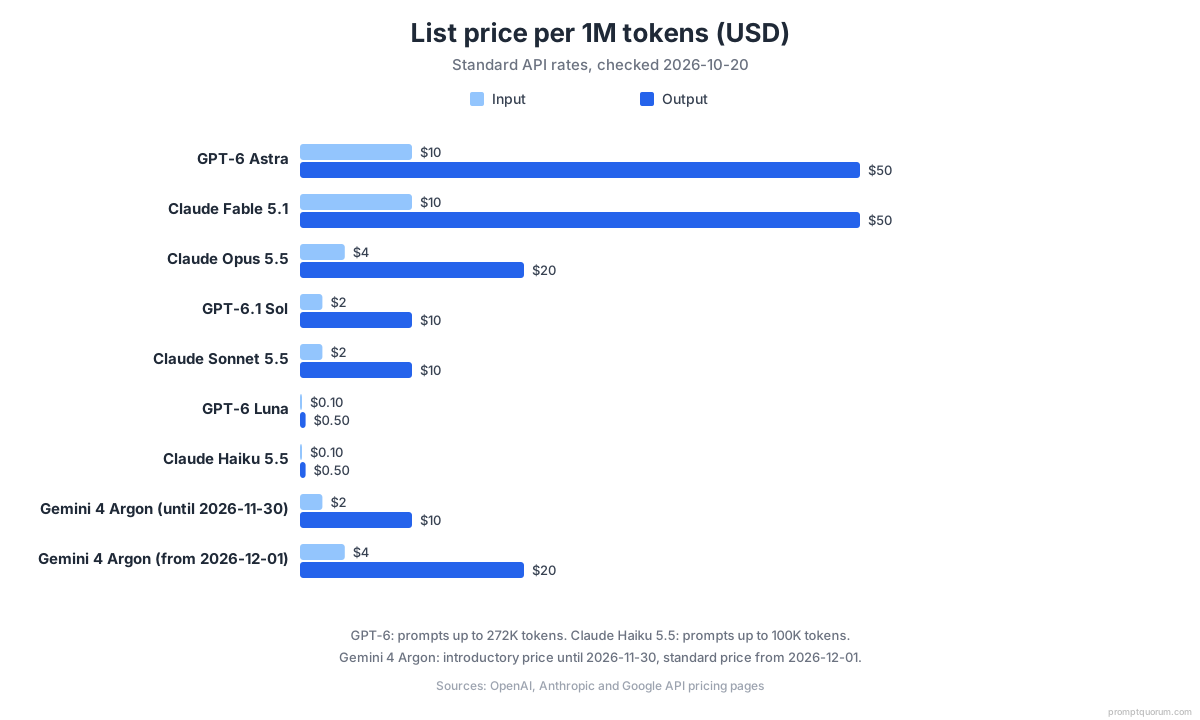
- Pricing (per 1M tokens, input/output): GPT-6 Astra $10/$50, Claude Opus 5.5 $4/$20, Gemini 4 Argon $2/$10 through 2026-11-30 ($4/$20 from 2026-12-01)
- Often favored for writing: Claude Opus 5.5 — concise, structured output (Anthropic suggests Claude Fable 5.1 for demanding reasoning and long-horizon agentic work)
- Tool integration: GPT-6 Astra — very large third-party ecosystem
- Lowest flagship list price (time-limited): Gemini 4 Argon at $2/$10 until 2026-11-30, then $4/$20, equal to Claude Opus 5.5; Gemini 3.8 Flash ($0.75/$3.75 through 2026-12-31, then $1.50/$7.50) or GPT-6 Luna ($0.10/$0.50) for high-volume work
- Required for China: DeepSeek or Baidu ERNIE — Western models restricted or high-latency
- Private/local: Ollama or LM Studio — no cloud API calls for inference
What Matters When Choosing an AI Model?
Model selection should start from your use case and constraints, not hype or leaderboard position. Here are the 7 dimensions that actually matter:
- Quality for your task: Does this model excel at writing, coding, analysis, or reasoning? Check performance on tasks similar to yours — not generic benchmarks.
- Cost per token and pricing tiers: Frontier models cost $2–50 per million tokens; budget models cost $0.10–3.75. Price scales by input and output tokens. See token economics in detail.
- Latency and rate limits: How fast does it respond? Can it handle your request volume? Some models are capped at 100 requests per minute; others support 10,000+.
- Context window size: GPT-6 Astra: about 1.05M tokens. Claude Opus 5.5: 1M tokens. Gemini 4 Argon: 1M tokens (all three roughly equal). Learn about context windows.
- Multimodal capabilities: Can it process images, audio, or video? GPT-6 Astra and Gemini 4 Argon support images well. DeepSeek and Baidu ERNIE focus on text.
- Ecosystem and integrations: How many third-party tools, plugins, and APIs support it? GPT-6 Astra has a very large ecosystem. Local models via Ollama or LM Studio support thousands of community integrations.
- Geography and data-residency rules: Is it available in your region? Does your data need to stay within a country or company network? Mainland China requires local models (DeepSeek, Baidu ERNIE) due to regulations and latency.
When Should You Use GPT-6 Astra?
GPT-6 Astra is OpenAI's frontier multimodal model — a strong fit for tool-heavy agentic workflows with a very large third-party integration ecosystem. Use GPT-6 Astra when tooling, integrations, and multimodal capabilities matter more than cost.
- Strengths: Excellent general reasoning and chat across all domains. Strong multimodal capabilities — reliably processes images, audio, and sometimes video. Mature tool-calling ecosystem with a very large third-party integration library. Widely used in production.
- Best use cases: Multi-step agent workflows. Complex chains where tool calling (APIs, databases, code execution) is required. Tasks needing screenshot or image analysis. OpenAI ecosystem projects (ChatGPT, Assistants API, Codex, fine-tuning).
- Trade-offs: Premium frontier models cost more per token ($10 input / $50 output per million); GPT-6.1 Sol ($2 / $10) is OpenAI's lower-cost near-Astra option. Output can be verbose — requires prompt discipline to enforce conciseness.
- Context window: about 1,050,000 tokens (handles ~800 pages of text).
When Should You Use Claude Opus 5.5?
Claude Opus 5.5 from Anthropic is well suited to careful reasoning, writing quality, and code refactoring, and is trained with Anthropic's Constitutional AI approach to safety. Use Claude when output quality, clarity, and trustworthiness matter most.
- Strengths: High-quality writing and summarization; outputs are concise, well-structured, and publication-ready. Excellent code understanding, refactoring, and explanation — often useful for catching bugs. Good long-context handling for research and document workflows. Safety-focused training approach, which some teams in regulated industries value.
- Best use cases: Reports, analyses, and knowledge work where structure and clarity are critical. Complex codebases and architecture discussions. Enterprise settings with compliance and safety requirements. Content that requires editing minimization.
- Trade-offs: Higher price point for top tiers; may be overkill for simple tasks. Some third-party integrations are newer than GPT-6 Astra equivalents.
- Going further: Anthropic also offers Claude Fable 5.1 ($10 input / $50 output per million tokens) for demanding reasoning and long-horizon agentic work. Anthropic suggests starting with Opus 5.5 and moving to Fable 5.1 when your evals on Opus 5.5 at higher effort still fall short.
- Context window: 1,000,000 tokens (handles ~800 pages of text).
When Should You Use Gemini 4 Argon?
Gemini 4 Argon from Google DeepMind is Google's flagship reasoning model, with a 1M-token context window and deep Google Workspace integration; its $2/$10 price is introductory (through 2026-11-30, then $4/$20). Use Gemini when processing many long documents or when your team lives in Google Workspace.
- Strengths: Very good coding performance at attractive price points — especially mid-tier Flash models. Strong long-context (1M tokens) and retrieval; excellent for research across many documents + live web search. Native integration with Google Workspace (Docs, Sheets, Drive, Gmail, Slides).
- Best use cases: Teams living in Google Workspace. Batch coding and data tasks where cost/performance ratio is critical. Research workflows combining local docs with web search. Processing 100+ pages of PDFs or transcripts.
- Trade-offs: Writing tone can feel more hedged or generic vs Claude or GPT. Outside Google's ecosystem, some integrations lag competitors.
- Context window: 1,000,000 tokens (handles ~800 pages of text).
Which AI model is best for coding in 2026?
Claude Opus 5.5 is often favored for code quality and refactoring; GPT-6 Astra is a strong fit for tool integration and multi-file reasoning; Gemini 4 Argon has the lowest flagship list price while its introductory pricing lasts; DeepSeek is the choice for mainland China developers. The "best" model for coding depends on your primary challenge: code quality, integration breadth, cost per token, or geography.
- GPT-6 Astra: Strong for multi-step coding tasks with tool use (file system access, APIs, shell commands). Excellent at reasoning across large codebases and generating complex workflows. Best if integrations with GitHub, AWS, APIs are critical.
- Claude Opus 5.5: Best for code review, refactoring, and architecture discussions. Often useful for catching subtle bugs. Preferred for maintaining existing codebases and explaining legacy code. Higher token cost but often reduces rounds of back-and-forth.
- Gemini 4 Argon: Attractive list price for batch coding tasks while introductory pricing lasts (data processing, utility scripts, automation). 1M context means you can load entire projects at once. Excellent for prototype-to-production velocity where cost matters.
- DeepSeek-V4: Positioned as a lower-cost alternative for coding. Best for mainland China developers and high-volume coding tasks (scaffolding, boilerplate, routine refactoring). Very strong on algorithm problems and competitive programming.
Best LLM for long context or large documents 2026?
All three frontier models support 1M context tokens (handles ~800 pages). The long-context gap has closed. For tasks requiring more than 1M tokens, consider local models like Llama 4 Scout (10M tokens). Choose based on cost, retrieval precision, and whether you need to load multiple files simultaneously.
- Gemini 4 Argon (1M tokens): Load entire codebases, legal document sets, or research archives. Web search integration lets you reference external sources within long context. Best for: due diligence reviews, regulatory analysis, knowledge base search, processing 100+ page PDFs.
- Claude Opus 5.5 (1M tokens): Excellent for detailed analysis and extracting nuanced information from long documents. Trade-off: highest cost per token, but quality may reduce revision rounds.
- GPT-6 Astra (~1.05M tokens): Strong for multi-step reasoning across long documents. Best when you need tool calling alongside long context (file system, APIs).
- Practical strategy: All three now support 1M tokens equally. Choose based on cost, output quality for your task, or tools ecosystem.
How to choose an AI model if you're in China or need low latency?
For users and data in mainland China, DeepSeek and Baidu ERNIE are usually the practical choice. Western frontier models (GPT-6 Astra, Claude, Gemini) are often restricted or high-latency in China due to network restrictions and regulatory requirements. Latency and compliance (data residency, content moderation) are major pain points. Using a Western model in mainland China can mean unavailable service, high latency for users, or regulatory exposure. Models hosted in mainland China avoid most of these issues; confirm current rules with legal counsel.
DeepSeek (frontier model, competitive coding): Competitive coding and reasoning performance, low pricing, excellent Chinese language support and mixed Chinese–English tasks. Hosted on mainland China infrastructure, so network latency is typically low. Best for developer workflows in mainland China and high-volume cost-sensitive workloads. Trade-offs: smaller ecosystem outside China, fewer third-party integrations vs GPT/Claude/Gemini.
Baidu ERNIE (enterprise and consumer): Tight integration with Baidu search and cloud, strong grounding in Chinese web content and enterprise data. Built to operate within mainland China's regulatory framework (content moderation, data residency, keyword filtering); compliance duties remain with the deploying organization. Best for consumer and enterprise apps targeting Chinese users, apps on Baidu Cloud infrastructure where compliance is non-negotiable. Trade-offs: primarily optimized for Chinese, English and other languages may lag Western frontier models.
GPT-6 Astra vs Claude Opus 5.5 vs Gemini 4 Argon: Quick comparison
This table compares 5 AI models across 8 key dimensions: general reasoning, writing, coding, long-context handling, multimodal support, cost efficiency, global ecosystem, and China access.
Dimension | GPT-6 Astra | Claude Opus 5.5 | Gemini 4 Argon | DeepSeek | Baidu ERNIE |
|---|---|---|---|---|---|
| General Q&A | Excellent global | Very good, cautious | Very good + retrieval | Strong, best for CN | Strong, best for CN |
| Writing | Great, sometimes verbose | Excellent structure & clarity | Good, neutral tone | Good, Chinese-first | Good, Chinese-first |
| Coding | Strong | Excellent, premium | Strong; low intro price | Very strong for CN devs | Good, applied business |
| Long context | Strong (~1.05M) | Strong (1M) | Strong (1M) + web | Good | Good with Baidu data |
| Multimodal | Leading (image/audio) | Good vision | Very strong (video/web) | Varies | Text + CN web |
| Cost efficiency | $10/$50 (highest) | $4/$20 | $2/$10 to 2026-11-30, then $4/$20 | Very cost-competitive | Competitive (CN enterprise) |
| Global ecosystem | Most extensive | Growing, esp. enterprise | Strong in Google world | Limited outside China | Strong in Baidu ecosystem |
| China access/latency | Often restricted | Often restricted | Often restricted | Native / low-latency | Native / required |
How Do You Pick the Right AI Model?
Start with your primary use case, layer in your constraints, then choose the model best suited to both.
If: General assistant, multi-tool agentic workflows. Then: Start with GPT-6 Astra. You need the most extensive tooling ecosystem and integrations.
If: Deep writing, analysis, complex code, or strong safety requirements. Then: Start with Claude Opus 5.5. Quality and trustworthiness matter more than cost.
If: Heavy Google Workspace usage, batch coding/data, or processing 100+ long documents. Then: Start with Gemini 4 Argon. Long context and ecosystem integration save time.
If: Users and data primarily in mainland China. Then: Start with DeepSeek (coding-heavy) or Baidu ERNIE (consumer/business apps). Western models are restricted or high-latency.
- Budget tight, volume high: Favor Gemini Flash / DeepSeek / smaller GPT models.
- Strict compliance, enterprise contracts: Claude enterprise, Baidu ERNIE for China.
- Need multimodal (screenshots, charts, audio): GPT-6 Astra or Gemini 4 Argon.
- Private data only: Local LLMs via Ollama or LM Studio (prompts are not sent to a cloud API).
How Do Costs and Token Limits Compare?
All major models are priced per input and output token, with rate limits based on your tier. Frontier models cost 10–100× more per token than budget models. Pricing varies by region (especially China).
- Frontier models (most expensive per token): GPT-6 Astra ($10 input / $50 output per million tokens), Claude Opus 5.5 ($4 input / $20 output per million tokens), Claude Fable 5.1 ($10 input / $50 output per million tokens).
- Lower-priced flagship (time-limited): Gemini 4 Argon ($2 input / $10 output per million tokens through 2026-11-30, then $4 / $20 from 2026-12-01, equal to Claude Opus 5.5) — the lowest of the three flagships while introductory pricing lasts.
- Cost-effective mid-tier: GPT-6.1 Sol ($2 input / $10 output), Gemini 3.8 Flash ($0.75 input / $3.75 output per million tokens through 2026-12-31, then $1.50 / $7.50) and GPT-6 Luna ($0.10 input / $0.50 output). Gemini 3.5 Flash-Lite is the efficiency tier below that.
- Competitive budget models: DeepSeek-V4 (low pricing), local models via Ollama/LM Studio (free, run on-device).
- Rate limits: Frontier models often start at 100 req/min; scaled tier can reach 10,000+ req/min. Local models depend on your hardware.
- Learn about context windows and how they affect model selection.
Why use multiple AI models instead of one in 2026?
Benchmarks and leaderboards change every few months. Different tasks are best served by different models. And geographic constraints (EU data residency, China latency) force multi-model stacks.
- Reason 1: Task-specific excellence. No model wins at everything. Claude is often favored for writing; Gemini for long-context research; GPT for multi-step reasoning. Route your tasks to the specialist.
- Reason 2: Cost optimization. Use small / budget models for high-volume repetitive work (summarization, categorization). Reserve frontier models for complex reasoning. Budget tiers list at a fraction of frontier prices, so routing suitable tasks to them can cut costs substantially while keeping quality where it matters.
- Reason 3: Regulatory and geographic constraints. EU requires EU data residency (Ollama local). China requires local models. Multi-model stacks let you comply with all constraints.
- Example stack: Claude for writing, Gemini for coding, GPT for agents, DeepSeek/ERNIE for China users. This is not complex — it is practical.
How Does PromptQuorum Help You Compare and Route Models?
PromptQuorum solves the pain of manual model switching by sending one structured prompt to all models simultaneously and comparing results automatically. No more copying prompts between tabs or guessing which model performed best.
- One structured prompt → many models simultaneously. Write your prompt once. PromptQuorum dispatches it to GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, DeepSeek, Baidu ERNIE, and local LLMs (Ollama, LM Studio) in parallel. See all responses side-by-side.
- Shared frameworks ensure fair comparison. Use the same prompt structure, constraints, and formats across all models. This eliminates the excuse "Claude got better output because I worded the prompt for Claude."
- Consensus and scoring view. PromptQuorum shows you which model writes best for your brand voice, which produces the most correct code, which handles your proprietary documents most reliably, and which model is fastest and cheapest for YOUR task.
- Routing rules: Send cheap / high-volume tasks to small or local models. Send complex reasoning to premium models. Automate model selection based on task type.
- Support for local LLMs. Connect Ollama or LM Studio for fully local inference. Prompts are not sent to a cloud API, but still check each tool's update and telemetry settings. Route sensitive tasks locally; send commodity tasks to cloud APIs.
- Stop guessing from YouTube benchmarks. Test your own tasks directly on your own data. That is the only truth that matters.
PromptQuorum Dashboard: See All Models at Once
Send one prompt, see outputs from GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, DeepSeek, and Baidu ERNIE — all in one view. Side-by-side comparison eliminates the pain of manual model switching.
Practical Recipes: 4 Ways to Use PromptQuorum for Model Comparison
Multi-model testing in PromptQuorum reveals which model works best for YOUR specific task, data, and brand — not generic benchmarks. Here are 4 concrete scenarios:
Recipe 1: Decide Which Model Writes Best for Your Brand Voice
You are writing product copy for a B2B SaaS landing page. The tone needs to be authoritative but accessible — no marketing fluff, no vague superlatives. Test the same brief on GPT-6 Astra, Claude Opus 5.5, and Gemini. See which model captures your brand voice best. Run it through PromptQuorum, score each output on tone, clarity, and adherence to your brand guidelines. The winner becomes your go-to model for copywriting. Example prompt: "Rewrite this feature description in our brand voice: paste your style guide + existing copy. Which model matches best?"
Recipe 2: Compare Coding Quality and Cost for Your Backend Stack
You have a Python codebase. Test: "Review this function for performance and bugs. Suggest refactoring." Run it through GPT-6 Astra, Claude Opus 5.5, and Gemini 3.8 Flash. Which catches the most bugs? Which refactoring is cleanest? Which is cheapest per request? Use PromptQuorum to score code quality. Gemini 3.8 Flash lists at roughly one-fifth of Claude Opus 5.5 per token ($0.75/$3.75 vs $4/$20), so check whether it catches enough of the issues for your use case. Example: "Optimize this database query for speed. What's the time complexity?" — routed to Claude for deep analysis, Gemini for budget-conscious iteration.
Recipe 3: Set Up a Global + China Stack (GPT / Claude / Gemini + DeepSeek / ERNIE)
Your product serves users worldwide and in mainland China. Route global users to GPT, Claude, or Gemini (your global stack). Route China users to DeepSeek or Baidu ERNIE (required for latency and compliance). Use PromptQuorum to test model performance on your actual user prompts in each geography. Ensure consistency while respecting regional constraints.
Recipe 4: Use Local LLMs for Private Data, Frontier Models for Final Polish
You have sensitive customer data. Step 1: Process locally with Ollama or LM Studio (prompts are not sent to a cloud API). Step 2: Send the refined output to Claude or GPT for final polish and quality check. This hybrid approach is cheap, private, and produces high-quality output. Test it in PromptQuorum to find the local model that works best for your pipeline.
How to Choose an AI Model for Your Task
- 1Define your task type: Is it factual/analytical (legal analysis, code review, data extraction) or creative/generative (brainstorming, copywriting, design ideation)? Factual tasks favor GPT-6 Astra or Claude Opus 5.5; creative tasks work across all frontier models.
- 2Match the model to speed/cost trade-offs: GPT-6 Astra is the broadest all-rounder but not the cheapest. Claude Opus 5.5 is well suited to long reasoning and accuracy. Gemini 4 Argon has the lowest flagship list price while its introductory pricing lasts and offers multimodal input with a 1M-token context window; Gemini 3.8 Flash, GPT-6.1 Sol and GPT-6 Luna are lower-cost tiers. Use PromptQuorum to benchmark all three against your specific prompt.
- 3Start with a frontier model (GPT-6.1 Sol, Claude Opus 5.5, or Gemini 4 Argon), then downgrade if possible: A task that works well on GPT-6.1 Sol might run just as well on GPT-6 Luna (~20× cheaper). Test your prompt on cheaper models once you have a working version.
- 4For local/private workflows, use Ollama or LM Studio, but accept lower quality: Local models handle private data without external API calls but produce lower accuracy than frontier models. Use a hybrid: local model for first pass, frontier model for quality check.
- 5For geographically distributed users, route by region: Global users (US, EU, Japan) → GPT-6 Astra / Claude / Gemini. China → DeepSeek or Baidu ERNIE (legal requirement). Use PromptQuorum to test each region's model independently.
- 6Test all three (or more) with PromptQuorum before committing: Send your prompt to GPT-6 Astra, Claude Opus 5.5, and Gemini 4 Argon simultaneously. Compare outputs to discover which model suits your task best.
Common Mistakes When Choosing an AI Model
❌ Choosing based on benchmark leaderboards instead of your actual task
Why it hurts: LMSYS Arena rankings and HumanEval leaderboards shift monthly. A model that leads on MMLU may lag on your specific coding, writing, or analysis task.
Fix: Test your actual prompts on 2-3 models before committing. Use PromptQuorum to compare on YOUR data.
❌ Assuming context window = quality on long documents
Why it hurts: All three frontier models support 1M tokens — context window parity has arrived. Filling a 1M context doesn't mean the model uses all of it well. The "lost in the middle" problem means information in the center of very long contexts may be missed.
Fix: For documents over 200 pages, chunk and summarize rather than pasting everything into one prompt, regardless of context window size. For documents requiring >1M tokens, consider local models like Llama 4 Scout (10M).
❌ Using a frontier model for every task
Why it hurts: GPT-6 Astra at $10/$50 per million tokens is about 13× more expensive than Gemini 3.8 Flash at $0.75/$3.75 (through 2026-12-31). Many classification, extraction, and summarization tasks produce comparable quality on cheaper models.
Fix: Start with the cheapest model. Upgrade to frontier only when the cheaper model measurably fails on your task.
❌ Ignoring geography and data residency.
Why it hurts: Sending EU personal data to US APIs requires SCCs. Serving mainland China users via GPT/Claude can add noticeable latency and may raise regulatory issues.
Fix: Route by geography. EU-sensitive data → local LLMs or EU-region API endpoints. China → DeepSeek or Baidu ERNIE. Global → any frontier model.
❌ Locking into one provider's SDK without an abstraction layer
Why it hurts: When a new model launches (and one launches every few months), you can't switch without rewriting your integration.
Fix: Use provider-agnostic SDKs (LiteLLM, PromptQuorum) or the OpenAI-compatible API format that Claude, Gemini, and local models also support.
Frequently Asked Questions
If I can only pay for one subscription, which should I choose?
Start with Claude Opus 5.5. It is the highest quality across writing, reasoning, and code. If your primary need is tool integration and multimodal (images/audio), choose GPT-6 Astra. If you have a Google Workspace-heavy team and cost is critical, choose Gemini. If your users are in mainland China, choose a model hosted in mainland China such as DeepSeek or Baidu ERNIE (usually necessary for latency and compliance).
How often should I re-evaluate my model choices?
Quarterly. Every 3–4 months, new models launch and leaderboard positions shift. Use PromptQuorum to re-test your most critical tasks on the latest models. What was best 6 months ago might no longer be optimal.
Can I mix multiple models inside one product or agent?
Yes — and you should. Route different tasks to different models: Claude for writing, Gemini for retrieval, GPT for agents. Use conditional logic: if this is a writing task, use Claude; if this is a retrieval task, use Gemini. This is how production systems work.
How do I think about vendor lock-in?
Vendor lock-in happens when your system depends on one model's API format, special features, or pricing. Protect yourself: (1) Use standard prompt structures that work across models. (2) Use abstraction layers (like PromptQuorum) that support multiple providers. (3) Test regularly on multiple models to catch vendor-specific drift. (4) For critical systems, support local models (Ollama, LM Studio) as a fallback.
Where do open-source local models fit into this picture?
Local models (Llama 4 Scout, Qwen3.6, Mistral Small 4, others via Ollama or LM Studio) are best for: high-volume repetitive tasks (classify, summarize, extract), private data (no API calls), cost-sensitive workloads, and testing before committing to API costs. They do not match frontier models on quality but excel on privacy and cost. Use them for the 80% of tasks that do not need frontier-level reasoning.
Is Claude better than ChatGPT?
For writing quality, code review, and structured reasoning, Claude Opus 5.5 is often preferred over ChatGPT (GPT-6 Astra), though results vary by prompt. For tool integration, multi-agent workflows, and a very large third-party ecosystem, GPT-6 Astra is a strong choice. Neither is universally better — the right choice depends on your specific task. Use PromptQuorum to test both on your actual prompts and compare results directly.
Which AI model is most accurate?
No single model is most accurate across all tasks. Claude Opus 5.5 is often favored for writing and structured analysis, GPT-6 Astra for tool-integrated reasoning, and Gemini 4 Argon for long-document research with live web grounding. Accuracy is task-specific — the only reliable test is running your actual prompts across all models and measuring the results.
What is the difference between GPT-6 Astra and GPT-6 Luna?
GPT-6 Astra is OpenAI's most capable GPT-6 model ($10 input/$50 output per million tokens). GPT-6.1 Sol offers near-Astra performance at $2/$10, and GPT-6 Luna is the cost-sensitive tier ($0.10/$0.50) — about 100x cheaper than Astra and 20x cheaper than Sol, with lower capability. Use GPT-6 Luna for classification, summarization, and high-volume tasks where frontier reasoning is not required. Use GPT-6.1 Sol for complex multi-step reasoning and agent workflows, and GPT-6 Astra for the hardest tasks where quality matters most.
Sources & Further Reading
Model strengths and pricing are drawn from each vendor's own published rates and from public benchmarks (LMSYS Arena, SWE-Bench, GPQA). Model capabilities and pricing change frequently — check official pricing pages for current rates, and test on your task before committing to production.