DeepSeek-R1 Distill VRAM Cheatsheet (2026)
Every DeepSeek-R1 distill, by quantization: 1.5B fits 4 GB, 7B/8B fit 8 GB, 14B fits 16 GB, 32B fits 24 GB, and 70B needs dual-GPU — all at the Ollama default Q4_K_M. Q8_0 roughly doubles the VRAM; FP16 roughly quadruples the Q4_K_M file size. This is the bookmark-it table for matching a distill to a card. Status: R1 is no longer DeepSeek's current generation (DeepSeek-V4 is), but these distills are separate open-weight releases that still run locally.
Key Takeaways
- ✓R1 is no longer DeepSeek's current generation — DeepSeek-V4 (Flash and Pro, MIT-licensed open weights) is. The R1 distills are separate open-weight releases and still run locally.
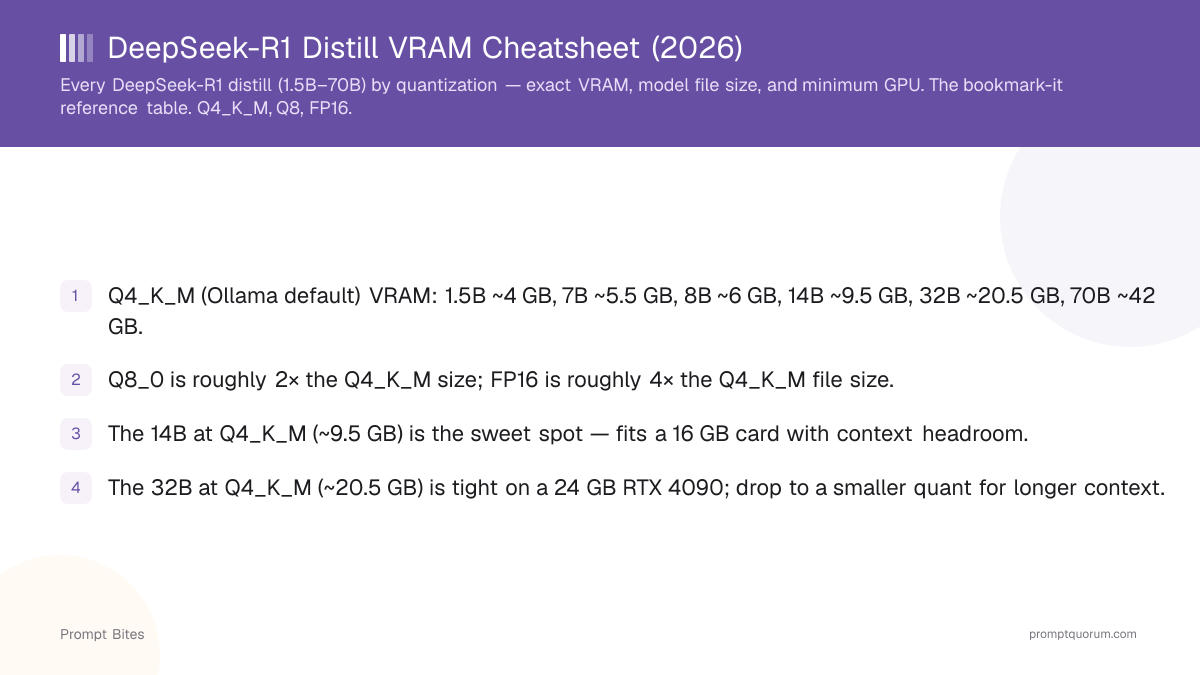
- ✓Q4_K_M (Ollama default) VRAM: 1.5B ~1.6 GB, 7B ~5.5 GB, 8B ~6 GB, 14B ~9.5 GB, 32B ~20.5 GB, 70B ~44 GB.
- ✓Q8_0 is roughly 2× the Q4_K_M size; FP16 is roughly 4× the Q4_K_M file size.
- ✓The 14B at Q4_K_M (~9.5 GB) is the sweet spot — fits a 16 GB card with context headroom.
- ✓The 32B at Q4_K_M (~20.5 GB) is tight on a 24 GB RTX 4090; drop to a smaller quant for longer context.
- ✓The full 671B DeepSeek-R1 is not on this table — it needs ~376–404 GB at Q4 (datacenter only).
- ✓These are R1 reasoning distills, not DeepSeek-V3 (a chat model).
This page contains links to third-party products for reference. PromptQuorum is not enrolled in any affiliate program — these are plain links that earn no commission. Clicking links and your next steps are entirely your own responsibility. These links do not represent any endorsement or verification by PromptQuorum.
Quick Answer
At Q4_K_M (Ollama default): 1.5B ≈ 1.6 GB, 7B ≈ 5.5 GB, 8B ≈ 6 GB, 14B ≈ 9.5 GB, 32B ≈ 20.5 GB, 70B ≈ 44 GB. Q8_0 is about 2× the Q4_K_M size and FP16 about 4×, so the 32B at FP16 needs a 80 GB-class setup.
- ▸1.5B: ~1.1 GB file, ~1.6 GB VRAM (or CPU) at Q4_K_M
- ▸7B: ~4.7 GB file, ~5.5 GB VRAM — RTX 3060 12GB
- ▸14B: ~9 GB file, ~9.5 GB VRAM — RTX 4060 Ti 16GB
- ▸32B: ~20 GB file, ~20.5 GB VRAM — RTX 4090 24GB (tight)
- ▸70B: ~43 GB file, ~44 GB VRAM — dual-GPU or 48 GB
- ▸Rule: Q8_0 ≈ 2× Q4_K_M; FP16 ≈ 4× Q4_K_M
DeepSeek-R1 Distill VRAM by Quantization
VRAM figures include a small allowance for context and KV cache on top of the raw file size. Q4_K_M is the Ollama default and a widely used size-to-quality trade-off for reasoning. Use Q8_0 only if you have spare VRAM and want a marginal quality bump; FP16 is rarely worth it locally.
| Distill | Q4_K_M (VRAM) | Q8_0 (VRAM) | FP16 (VRAM) | Min GPU (Q4_K_M) |
|---|---|---|---|---|
| 1.5B | ~1.6 GB | ~2.5 GB | ~4.2 GB | Any 4 GB GPU / CPU |
| 7B (Qwen2.5) | ~5.5 GB | ~8.7 GB | ~15.6 GB | RTX 3060 12GB |
| 8B (Llama 3) | ~6 GB | ~9 GB | ~16.6 GB | RTX 3060 12GB |
| 14B (Qwen2.5) | ~9.5 GB | ~17 GB | ~31 GB | RTX 4060 Ti 16GB |
| 32B (Qwen2.5) | ~20.5 GB | ~36 GB | ~67 GB | RTX 4090 24GB (tight) |
| 70B (Llama 3) | ~44 GB | ~76 GB | ~142 GB | Dual-GPU / 48 GB |
Which Quantization Should You Pick?
**Use Q4_K_M for almost everything** — it is the Ollama default and keeps reasoning quality high while fitting the most models per GB. Pick it unless you have a specific reason not to.
**Use Q8_0 only with spare VRAM** — it roughly doubles the footprint for a marginal quality gain that usually changes little in a reasoning answer. Worth it on a 24 GB card running the 14B, not much else.
**Skip FP16 locally** — at roughly 4× the Q4_K_M size it pushes the 32B to 80 GB-class hardware for little practical reasoning benefit over Q8_0 in most local setups.
14B on a 16 GB Card: Which Quant Fits
**On a 16 GB GPU, run the 14B at Q4_K_M, Q5_K_M or Q6_K — not Q8_0.** The Ollama Q4_K_M file is 9.0 GB, leaving ~6 GB for context; Q5_K_M (~10.5 GB) and Q6_K (~12.1 GB) still fit with a moderate context window.
**Q8_0 does not fit comfortably.** The Ollama Q8_0 file is 16 GB — the whole card before any KV cache — so part of the model spills into slower system RAM.
**Ollama ships only Q4_K_M, Q8_0 and FP16 tags for the distills.** For Q5_K_M or Q6_K, pull a GGUF file from Hugging Face: `ollama run hf.co/
**An RTX 4070 Laptop has 8 GB of VRAM, not 16 GB.** Use the 7B or 8B distill at Q4_K_M (4.7–4.9 GB files). The 14B (9 GB) partly offloads to system RAM and slows down sharply.
**The `deepseek-r1:8b` tag is not the Llama distill.** Its 5.2 GB size in the Ollama tag list matches the Qwen3-8B-based R1-0528 build, not the 4.9 GB Llama distill; the Llama 3 distill in the table is `deepseek-r1:8b-llama-distill-q4_K_M`.
V3 vs R1: Don't Confuse Them
**DeepSeek-V3 is a chat model; DeepSeek-R1 (and these distills) are reasoning models.** This table is for the R1 reasoning family only. If you are looking for V3, it is a 671B MoE chat model that is also not consumer-runnable — see the [DeepSeek-V3 hardware bite](/prompt-bites/deepseek-v3-local-hardware-requirements).
**Update:** DeepSeek's current generation is DeepSeek-V4 (Flash and Pro), released as open weights under the MIT license (preview: April 24, 2026). DeepSeek's API now serves V4: the deepseek-chat (V3-generation) and deepseek-reasoner (R1-generation) aliases were announced as fully retired after July 24, 2026. The R1 distills are separate open-weight releases that were not part of that notice, and they still run locally. V4 itself is not a consumer-GPU model: V4-Pro has 1.6T total parameters (49B active) and the original V4-Flash 284B (13B active), so even at 4-bit precision (parameter count × 0.5 byte) the weights alone need roughly 140 GB (Flash) to 800 GB (Pro), and DeepSeek's model cards list no GPU requirement. For reasoning on a single consumer GPU, the distills remain the practical pick.
Related Guides
- ▸Best DeepSeek Distill for Your GPU — match your card to a distill plus the Ollama command and expected tok/s
- ▸Best Local Reasoning Model 2026: DeepSeek-R1 Ranked — the full ranked guide with benchmarks
- ▸DeepSeek-V3 Local Hardware Requirements — the V3 chat-model counterpart
Frequently Asked Questions
Is DeepSeek-R1 still DeepSeek's current model?▾
What is the VRAM for DeepSeek-R1-Distill-Qwen-32B?▾
How much does Q8_0 add over Q4_K_M?▾
Can I run the 70B distill on one GPU?▾
Is the full DeepSeek-R1 on this table?▾
How much VRAM does DeepSeek-R1 14B need when quantized?▾
Can I run DeepSeek-R1 14B on 16 GB of VRAM?▾
Which DeepSeek-R1 distill fits an RTX 4070 Laptop (8 GB)?▾
Want the full breakdown?
Read the complete guide →Related Prompt Bites