PromptQuorumBuilt for humans. Structured for AI.

PromptQuorum hands-on test Β· Caelum Β· 21 October 2026

Caelum on an Android Phone: Reads a Parcel Slip, Stumbles on Facts and Logic (Other AIs Slipped on the Logic Too)

The first PromptQuorum hands-on test run on a phone instead of a Mac. A OnePlus 8 Pro with 12 GB, a 1,020 Mo model download and no word on which model it is. The aim was simply to see how the app works and what is possible; setup caused no problems.

Related: PromptQuorum review of Caelum Β· Local AI app directory

Figure 1Chat home screen at 10:39, light theme. Observed.

Verdict

General assessment

Test completed: the tester went through what the app offers on a OnePlus 8 Pro with 12 GB. Caelum downloaded 1,020 Mo of model data in about three minutes, then handled chat, photo input and web search, but never says which LLM it downloaded. The tester was impressed that it described a photographed parcel slip. In the two accuracy checks he ran, the answers failed: a news question returned an assassination that a third-party source contradicts, and a hard logic prompt was rated 5/25 by ChatGPT, used as the judge. ChatGPT rated three other AIs (Grok in its free version, Claude Opus 5.5, Claude Fable 5.1) better on the same prompt but found logic errors in each. The tester would not keep the app. Offline operation was not tested: it is unclear when the app's web interface is on or off and what it does.

Fit for the tester's use

Not a fit for the tester, who works with frontier models and with local models on a Mac: in his view free frontier services do far more, and a 1 GB file on the phone 'doesn't deliver most of the time'. Fit for other users is not established: the offline claim and data handling were not tested.

  • ObservedFirst test of this series on a phone: a OnePlus 8 Pro running Android. The seven earlier tests ran on a 24 GB Mac.
  • MeasuredFirst run: the app downloads 1,020 Mo of data with a progress bar, a size counter and an ETA, and reached the chat screen about three minutes after the first screenshot.
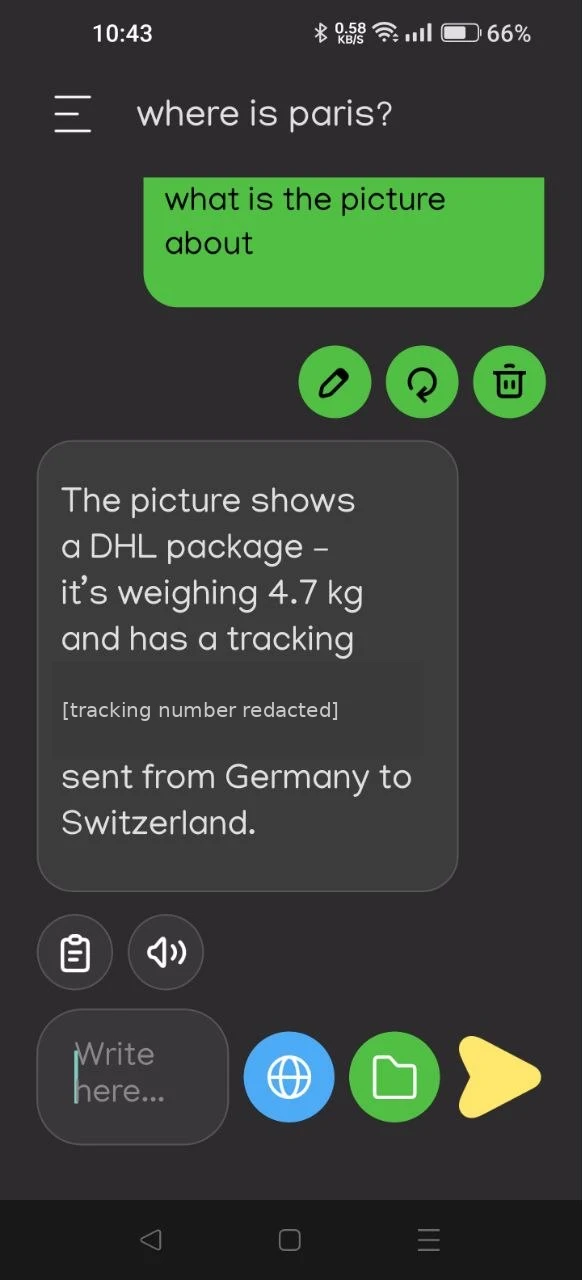
  • ObservedPhoto input worked: asked 'what is the picture about' with a photographed DHL parcel slip, it answered with carrier, weight, a tracking number and a route. The tester doubted the destination.
  • ObservedThe app never says which LLM it downloaded: no model name appears on the download screen or in the chat.
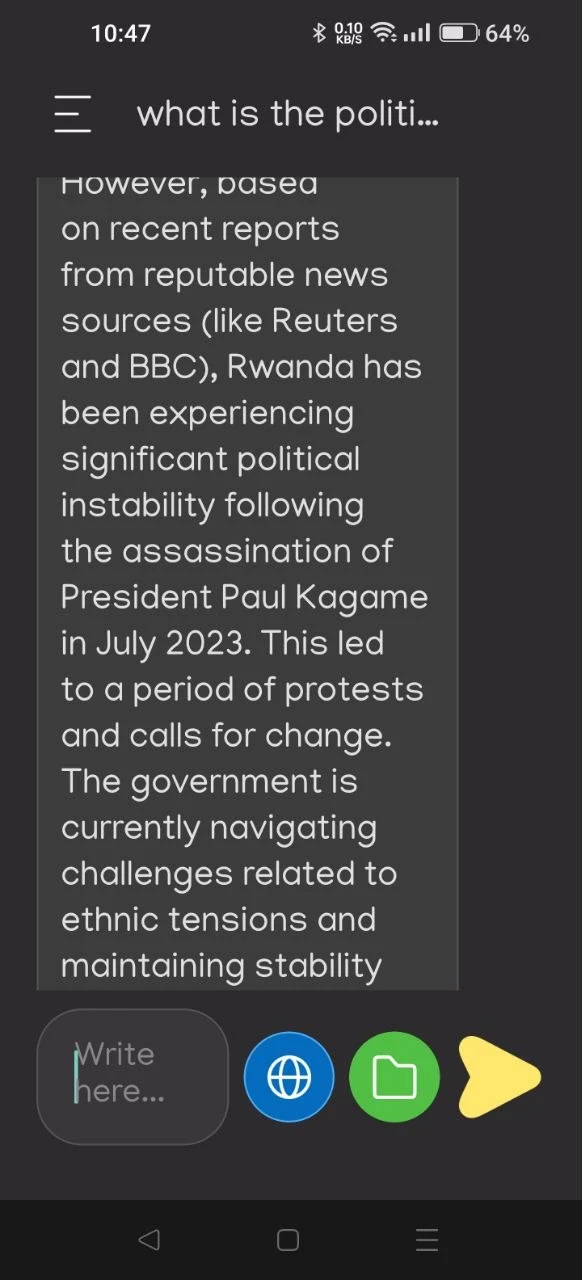
  • ObservedOn a question about Rwanda it stated that President Paul Kagame was assassinated in July 2023. A Google AI Overview, seen by the tester, says he has been in office since 2000 and was re-elected in July 2024.
  • Third partyChatGPT, used as judge, scored the app's answer to a hard logic prompt 5/25 ('qualitative evaluation, not a standardized benchmark score'). The tester did not check the logic himself. Three other AIs (Grok in its free version, Claude Opus 5.5, Claude Fable 5.1) were rated better by ChatGPT, but each still made logic errors.
  • Tester viewHe would not keep the app: free frontier services do far more, and the local-AI side is hardly explained in the app.

Scorecard Status: Completed

  • Installation4/5Proposed from the evidence, the tester's to confirm. The first-run download showed size, progress and an ETA, and no setup problems were recorded. The Play Store install step itself was not screenshotted.
  • Onboarding and model choicen/aNot scored. No model choice appears in the screenshots and the app never says which model was downloaded.
  • Core function2/5Proposed from the evidence, the tester's to confirm. Photo description impressed the tester; one false news answer and a weak logic answer (judged by ChatGPT, not checked by the tester) pull the score down.
  • Guidance and iterationn/aNot tested. Edit, regenerate, delete, copy and read-aloud buttons are visible; only copy was used.
  • Performancen/aNot timed. The tester estimates more than one minute for the logic answer; the phone has 12 GB, the Android version is not recorded.
  • Documentationn/aNot tested.
  • Trust and privacyn/aNot audited. Offline use (airplane mode) was not tested.
  • Uninstalln/aNot tested.

Scores are proposals derived from the evidence below (1 = poor, 5 = very good). They are the tester's to confirm. Only two dimensions are scored; the others were not scored.

Test details

App
Caelum: Local AI Assistant (Google Play package com.reactnativeai). Observed
Version
1.3.1. The tester downloaded the app on 21 October 2026; the Google Play listing, read by PromptQuorum the same day, shows v1.3.1, last updated 14 August 2025 (older than one year). Third party
Tester
Hans Kuepper, founder of PromptQuorum
Started
21 October 2026, 10:36 on the phone clock (status bar). The date comes from the notes file's creation time, 10:37 local. Assumption
Ended
At least 10:56 on the phone clock (status bar). The later cross-checks on other models carry no clock. Measured
Hardware
OnePlus 8 Pro with 12 GB of memory (the tester calls it 12 GB VRAM; on a phone the memory is shared). Chip and battery health not recorded. Third party: a 2020 phone with a Snapdragon 865 and 8 or 12 GB of RAM (not verified here). Observed
System
Android; version not recorded. Network: the status bar shows 5G at 10:36 and a Wi-Fi icon from 10:39. Observed
Source
Not recorded. Downloaded on 21 October 2026; Google Play is assumed. Assumption
Download
1,020 Mo of model data on first start (as shown by the app); 1,020 Mo is about 1.0 GB. Measured
Why tested
To see what a phone-only AI chat app does in practice. This is the first PromptQuorum hands-on test run on a phone, and on Android: the seven earlier tests (Draw Things, BoBe, Page Assist, Msty Studio, Unsloth, DiffusionBee, LTX Desktop) ran on a 24 GB Mac. That no one else has hands-on tested an on-device LLM app on an Android phone was not checked; the claim is 'first in this series'. Observed
Objective
No fixed goal: just see how the app works and what is possible. Setup was not the question and no setup problems were recorded.
AI help used
ChatGPT wrote the logic prompt and judged the answers. Grok (free version), Claude Opus 5.5 (medium) and Claude Fable 5.1 (high) were given the same prompt as cross-checks. The tester confirmed these names. The ChatGPT screenshots are not used on this page.

Every statement carries a label:ObservedMeasuredTester estimateVendor claimThird partyAssumptionTester viewTester errorWhat the labels mean

Disclosure. The tester founded PromptQuorum, a content site and directory about local AI apps. Caelum has a directory entry and an existing, separately written review on the site (listed 19 October 2026). The notes do not record whether the tester read that review before testing. No contact with the maker, no payment and no sponsorship are recorded.

Raw notes PDF: to be added

Six moments that shaped this test

Wow, this little app can read pictures and can give me the content of the pictures.

Tester notes, quoted as written (they were dictated). The first quote follows the photographed DHL slip; the second is about small local models in general; the third is his reason for not keeping the app, and '100 times' is a figure of speech, not a measurement.

How the test went

The listing

Third party

The PromptQuorum directory lists Caelum as a free, closed-source Android chat app that says it runs AI offline, with document questions and optional web search. It records no named model, a website that no longer resolves, 10K+ Play downloads, Android 7.0+ and no update since 14 August 2025 (data read 19 October 2026; the update date is older than one year).

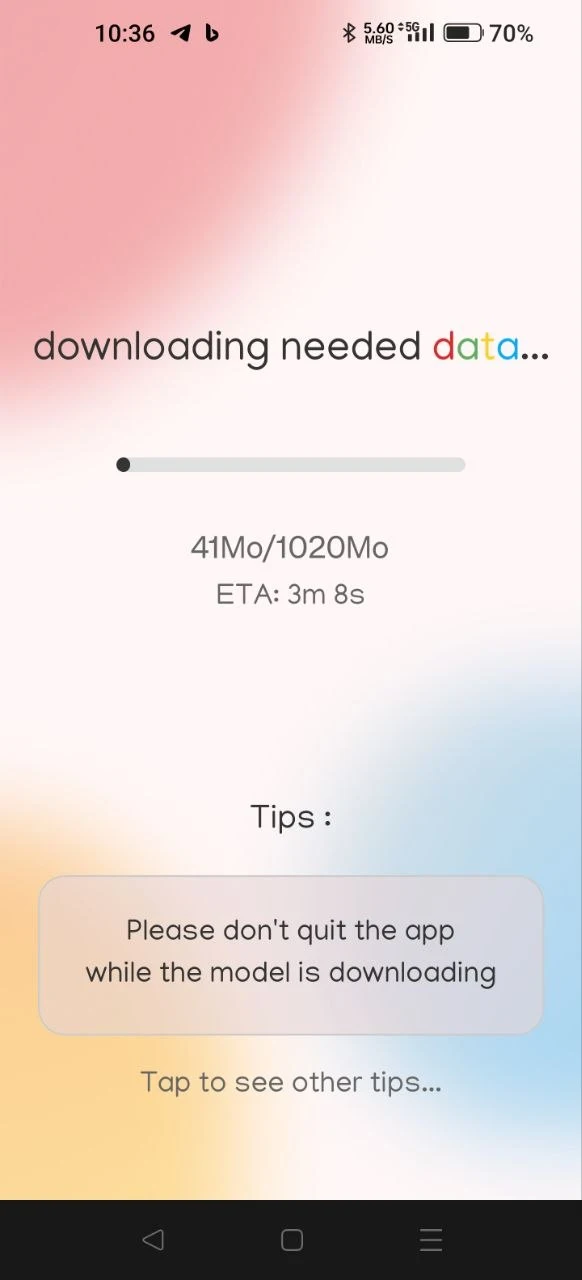
First launch and download (10:36 to 10:39)

Measured

The first screen reads 'downloading needed data...', 41 Mo/1020 Mo, ETA 3m 8s, with a tip box and 'Tap to see other tips...'. The 5.60 MB/s figure is the status bar's own indicator.

Figure 2First-run download at 10:36. Observed; the 5.60 MB/s figure is the status bar's.
Observed

The app never says which LLM it is downloading: the screen shows only 'downloading needed data...'.

Assumption

The next screenshot, at 10:39, shows the chat home screen. The end of the download was not screenshotted, so 'about three minutes' is derived from the two clocks.

Tester view

The tester called the screen 'very colorful, very beautiful' and the input area 'a little bit crowded'.

Observed

The unit shown is 'Mo', the French abbreviation for megabyte, while the rest of the visible text is English. The tester calls the download 'one gigabyte'; 1,020 Mo is about 1.0 GB.

Home screen (10:39)

Observed

'How can I help you today?', two suggested prompts ('What are the benefits of meditation?', 'Explain quantum physics in simple terms'), and an input row: text field, blue globe button, green folder button, yellow send arrow.

Figure 1Chat home screen at 10:39, light theme. Observed.
Assumption

The folder button is how the photo was attached; the notes do not say.

Photo input (10:43)

Observed

The tester sent a photographed DHL slip with the prompt 'what is the picture about'. The answer: a DHL package, weight 4.7 kg, a tracking number, 'sent from Germany to Switzerland'.

Figure 3Answer to 'what is the picture about' at 10:43. Observed; tracking number redacted by PromptQuorum.
Tester view

He was impressed that such a small app reads pictures, and wrote: 'Switzerland, not sure where it got that idea.'

Assumption

Whether the weight, tracking number and route match the slip is not recorded: the slip itself is not in the notes. Only the destination was questioned.

Observed

The chat title reads 'where is paris?' while the visible message is 'what is the picture about'. The title is the chat's first question: the tester had added two further questions, including the photo question, to the same chat.

Observed

Action buttons: edit, regenerate and delete under the user message; copy and read-aloud under the answer. The screen was in dark theme at 10:43 and in light theme at 10:39; how the theme changed is not recorded. The tester: 'it has a dark theme. Nice.'

The Rwanda question (10:47)

Observed

In a new chat titled 'what is the politi...' the visible part of the answer says Rwanda 'has been experiencing significant political instability following the assassination of President Paul Kagame in July 2023', citing 'reputable news sources (like Reuters and BBC)'. No links are visible in the screenshot. The full question was not captured; it is assumed to be a question about the political situation in Rwanda.

Figure 5The false claim at 10:47. Observed; contradicted by a third-party source.
Third party

A Google AI Overview, which the tester captured, says Kagame has been in office since 22 April 2000 and won re-election in July 2024; Google's own note says AI responses may include mistakes. The Overview shows a photo of a real person, so the screenshot is not published here.

Third party

A further web search by PromptQuorum on 21 October 2026 found his official site and an election report, and no report of an assassination. This is a limited check.

Logic stress test and cross-check (10:49 onward)

Observed

ChatGPT produced a prompt titled 'Advanced Logic Stress Test: The Blackout Protocol', described as testing constraints, temporal reasoning, contradictions and multi-step deduction. The tester pasted it into Caelum.

Tester estimate

Caelum wrote 'a big report' and a minute later was still writing; it ended by offering a deeper dive. The text of its answer was not captured; the only visible fragment, in a pasted preview, begins '1. Feasibility Ve...' and 'The plan is highly improbable to...'.

Third party

The tester pasted the answer into ChatGPT. Its verdict: 'The AI sounds analytical, but it makes several serious logical errors. I would score this response quite poorly', with the 'correct-looking conclusion β€” no valid plan β€” without establishing the actual contradiction'. Its scores: 5/25 overall (constraint comprehension 2/5, formal deduction 1/5, temporal reasoning 1/5, proof quality 0/5, instruction following 1/5), 'not a standardized benchmark score'. ChatGPT also wrote: 'One important correction to my own earlier analysis'.

Third party

To test whether the prompt itself was unfair, the tester ran it through Grok (free version), Claude Opus 5.5 (medium) and Claude Fable 5.1 (high) and showed each answer to ChatGPT. ChatGPT rated the later answers better ('substantially better', 8/10 on logical deduction in one case) and still found errors in each, for example a count of 12 valid schedules that 'are actually 13', and a minimum-repair proof 'not yet rigorous enough'.

Tester estimate

Opus answered 'in less than one minute'; Grok was still working after about three minutes. Neither was timed.

Tester view

His rule: always cross-check, never trust a single model, 'especially not the smaller one'. He also says Fable was the first to explain what the task was.

The decision

Tester view

The tester sums up: reading pictures is 'incredible' for a small model; web search is unusual among comparable apps (not checked by PromptQuorum); quality is mixed, which is no surprise from a 1 GB model. The local nature of the AI 'is actually not stressed at all', and he doubts a user would know the model runs locally.

Tester view

Would he keep it? 'No, I don't see the point.' Free services on frontier models do much more, so the file is not worth the space.

Phone clock and battery

Measured

10:36: first screen, 41 Mo of 1,020 Mo downloaded, ETA 3 m 8 s, 5.60 MB/s, 5G, battery 70%.

Measured

10:39: chat home screen, light theme, Wi-Fi icon, battery 67%.

Measured

10:43: photo question, dark theme, web search starts, battery 66% and 65%.

Measured

10:47: Rwanda answer, battery 64%.

Measured

10:49: ChatGPT writes the logic prompt (in the ChatGPT app), battery 63%. 10:55 to 10:56: ChatGPT judges Caelum's logic answer (in the ChatGPT app), battery 59%.

Assumption

Battery fell from 70% to 59% in 20 minutes with the screen on and with the ChatGPT app in use for part of that time, so none of it can be assigned to Caelum. Between 10:39 and 10:47, mostly inside Caelum, it fell from 67% to 64%. No memory chart is possible because the app's memory use was not recorded (the phone has 12 GB). Throughput readings in the status bar (0.03 to 0.58 KB/s in the chat screenshots) are single snapshots, not a traffic log, and do not show whether the app is offline.

Claims versus what the tester saw

ClaimSourceObservedLabel
Runs AI offlineGoogle Play listing and developer's privacy page, via the PromptQuorum review (read 19 October 2026)Not tested (no airplane-mode run): it is unclear when the app's web interface is on or off and what it does. The 1,020 Mo download fits an on-device model (assumption). None of the five app screenshots shows the words 'local' or 'offline'; the tester says the app does not stress it.Assumption
Document questionsGoogle Play listing, via the PromptQuorum reviewNot tested. The tester used the folder button for the photo and did not find another documents function (assumption: documents would go through the same button).Assumption
Optional web searchGoogle Play listing, via the PromptQuorum reviewSeen working: 'Searching the web...' appeared and an answer followed. The one answer checked was false in a key claim (see CAE-09).Observed
Free, no accountGoogle Play listing, via the PromptQuorum reviewNo sign-in screen appears in the screenshots; the rest of the app was not explored.Observed
Works on Android 7.0+Google Play listing, via the PromptQuorum reviewNot tested; the Android version of the test phone is not recorded.Observed

Usage log

#TaskModelResultTimeStatusFigures
1First-run model downloadNot named1,020 Mo downloaded, chat screen about three minutes laterabout 3 min (clocks)PassFig. 2
2Describe a photographed parcel slipNot namedCarrier, weight (4.7 kg, as stated by the app), tracking number and route returned; destination doubted, rest uncheckedNot timedPartialFig. 3
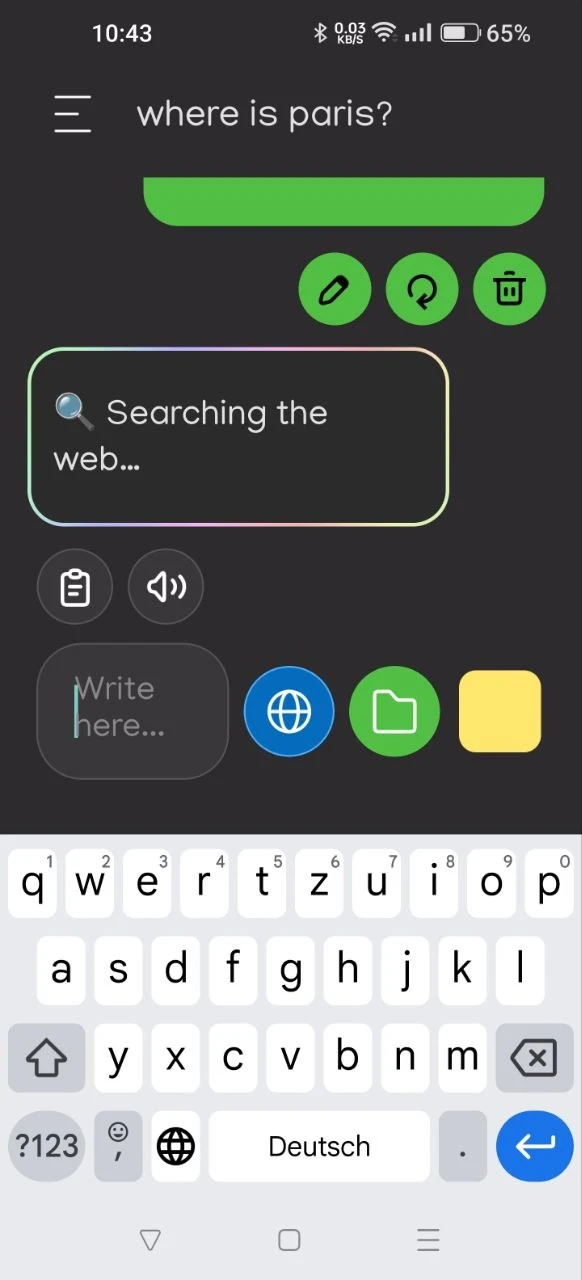
3Web searchNot named'Searching the web...' shown; globe turns darker blue; state of the toggle unclearNot timedPartialFig. 4
4Question on Rwanda (web search apparently on)Not namedReports an assassination of President Kagame in July 2023; contradicted by a third-party sourceNot timedFailFig. 5
5Hard logic prompt (Blackout Protocol)Not namedLong structured report; judged poor by ChatGPT (5/25 on ChatGPT's own scale), not checked by the testerMore than 1 min (tester estimate)Fail-
6Copy answer to another appNot namedCopy button worked; answer pasted into ChatGPTNot timedPassFig. 3

Where the tester got it wrong

  • Tester errorLeft gaps in the record: the Android version and where the app was installed from. Only the phone clock in the screenshots times the test.
  • Tester errorDid not capture Caelum's own logic answer, the photographed slip, or the full Rwanda question. The weight, tracking number and route cannot be checked, and the logic result rests on ChatGPT's description of the answer.
  • Tester errorDid not check the logic puzzle himself ('why use my brain if I have ChatGPT?'). ChatGPT wrote the puzzle and judged the answers; its statements about the schedule count differ between screenshots (13 in one, 'consistent with 12' in another), and which answer each refers to is unclear. The judge was therefore not independent and not verified.
  • Tester viewThe tester accepts that the prompt may have been too hard for a 1 GB model ('maybe the test was too difficult') and that frontier models are an unfair yardstick; this report keeps that caveat.

Findings register

IDFindingCategoryLabelSeverityFigures
CAE-01The first run downloads 1,020 Mo with a progress bar, size counter and ETA (3 m 8 s at 5.60 MB/s); the chat screen appeared about three minutes after the first screenshot.SetupMeasuredPositiveFig. 2
CAE-02The download screen asks users not to quit the app during the download and offers rotating tips.SetupObservedLowFig. 2
CAE-03Photo input worked: a photographed DHL slip was described with carrier, weight (4.7 kg, the app's statement), tracking number and route.Core functionObservedPositiveFig. 3
CAE-04The destination in that description ('Switzerland') was doubted by the tester; the other details were not checked.AccuracyTester viewMediumFig. 3
CAE-05The chat is titled 'where is paris?', the first question asked in it; the photo question was one of two further questions the tester added to the same chat, so the title does not match the visible message.Chat handlingObservedLowFig. 3
CAE-06The web-search button has two blue shades (lighter at rest, darker while searching) and no label; the tester could not tell when it is on.InterfaceObservedMediumFig. 4
CAE-07During web search the send arrow turns into a yellow square and a rainbow-bordered 'Searching the web...' box appears.InterfaceObservedLowFig. 4
CAE-08A dark theme exists. The screen was light at 10:39 and dark at 10:43; how it changed is not recorded.InterfaceObservedPositiveFig. 1, Fig. 3
CAE-09On a question about Rwanda the app stated that President Paul Kagame was assassinated in July 2023 and cited Reuters and BBC without visible links; a third-party source says he is in office, re-elected July 2024.AccuracyObservedHighFig. 5
CAE-10The app does not say which LLM was downloaded: no model name appears on the download or chat screens, and the directory records no named model either.TransparencyObservedMedium-
CAE-11ChatGPT scored the answer to a hard logic prompt 5/25 (its own scale) and said it reached a correct-looking conclusion without establishing the contradiction.Core functionThird partyHigh-
CAE-12Three other models given the same prompt were judged better by ChatGPT, which still found errors in each; the judge was not verified by the tester.Test designThird partyMedium-
CAE-13The logic answer ran longer than one minute and ended with an offer of a deeper dive that the tester did not want.PerformanceTester estimateLow-
CAE-14The app does not stress that the AI runs on the phone; the tester doubts a user would know. None of the five app screenshots shows 'local' or 'offline'.TransparencyTester viewMediumFig. 1
CAE-15Offline operation (the vendor claim) was not tested: it is unclear when the app's web interface is on or off and what it does.Trust and privacyTester viewMedium-
CAE-16Edit, regenerate, delete, copy and read-aloud buttons are present; copy worked for moving an answer to another app.InterfaceObservedPositiveFig. 3
CAE-17The tester would not keep the app: free frontier services do more and the 1 GB file is not worth the space.VerdictTester viewHigh-
CAE-18Battery fell from 70% to 59% between 10:36 and 10:56 with the screen on; part of that time was spent in the ChatGPT app, so it cannot be assigned to Caelum.PerformanceMeasuredLow-

Severity is the impact on a first-time user. Proposed, not measured.

Who it is for

Likely fit

  • Third partyPer the PromptQuorum review (not verified by this test): Android users who want a free, account-free chat and document app and accept a closed-source project with no named model and no update since 14 August 2025.

Likely poor fit

  • Tester viewPer the tester: nobody he can name; he would not keep it.

Retest. Retest after a new Play Store version (the last update is from 14 August 2025, older than one year), once the maker names the model, with an airplane-mode run on the same phone, and on a second Android phone with a known Android version.

They always package everything beautifully, and packaging something beautiful makes people believe that it's right. But then it is not right.

Tester notes, quoted as written (they were dictated). The first quote follows the photographed DHL slip; the second is about small local models in general; the third is his reason for not keeping the app, and '100 times' is a figure of speech, not a measurement.

Frequently asked questions

Does Caelum run on an Android phone without setup problems?

In the test, yes: the first run downloaded 1,020 Mo with a progress bar and ETA, and the chat screen appeared about three minutes after the first screenshot on a OnePlus 8 Pro. The phone has 12 GB; the Android version was not recorded. Measured

Which LLM does Caelum use?

The app does not say. It downloads 1,020 Mo on first start, and no model name appears on the download screen or in the chat; the PromptQuorum directory records none either. Observed

Can Caelum read a photo?

Yes, in one try. Given a photographed DHL parcel slip it named the carrier, weight, a tracking number and a route; the tester doubted the destination and did not check the rest against the slip. Observed

Is Caelum's web search reliable?

Not in the one answer checked. It said President Paul Kagame was assassinated in July 2023; a Google AI Overview and a further check say he is in office. The web-search button also has two similar blues and no label. Observed

How did Caelum do on a hard logic prompt?

Poorly according to ChatGPT, used as judge: 5/25 on its own scale. The tester did not check the logic himself and Caelum's answer was not captured, so this rests on ChatGPT's description. Third party

Does Caelum work offline?

Not tested. The vendor claims offline operation, but it is unclear when the app's web interface is on or off and what it does, so no airplane-mode run was made; none of the app screenshots shows the words 'local' or 'offline'. Vendor claim

Background on the maker

Not hands-on. The item below comes from the PromptQuorum directory entry for Caelum, read on 19 October 2026, and was not independently verified.

  • Third partyUnverified directory data read 19 October 2026: closed source, package com.reactnativeai, 10K+ downloads on Google Play, Android 7.0+, v1.3.1 updated 14 August 2025, a website that no longer resolves. The maker is not named in the tester's notes; the PromptQuorum review of Caelum says who the developer is, from a public profile, and the tester did not check this.

More hands-on tests

How to read the labels

Observed
Seen first-hand in the app, a screenshot or the tester's notes.
Measured
A value read from a dialog, counter or tool, with the number given.
Tester estimate
The tester's own estimate; not timed or counted.
Vendor claim
Stated by the app, its store listing or its website; not verified.
Third party
From another source (an AI assistant, an article); not verified here.
Assumption
An inference. It may be wrong.
Tester view
The tester's judgment or opinion.
Tester error
Where the tester made a mistake or missed something.

Sources

  • Tester's hands-on notes and screenshots, 21 October 2026 (original Word document 'Caelum App on Android'; PDF of the raw notes to be added).
  • Google Play: Caelum: Local AI Assistant (https://play.google.com/store/apps/details?id=com.reactnativeai), as recorded in the PromptQuorum directory on 19 October 2026.
  • PromptQuorum directory entry and review of Caelum (slug: caelum).
  • Election report, AFP via EWN, 16 July 2024 (ewn.co.za/2024/07/16/rwandas-kagame-wins-fourth-term-with-99-of-vote), read 21 October 2026: President Kagame re-elected with 99% of the vote.
  • Google AI Overview on Paul Kagame and ChatGPT answers, as captured by the tester (not republished).

Test ID pq-test-caelum-2026-10-21 Β· Test standard v0.1 Β· Raw notes PDF: to be added

How I test apps β€” and why there is no fixed standard β€” These tests are my personal views, not guarantees.

MCP