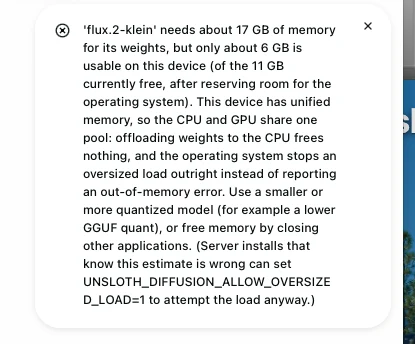
Figure 1Refusal to load the picture model flux.2-klein. The app reports about 17 GB needed, about 2 GB usable (7 GB currently free, minus room for the operating system). It names an override variable, UNSLOTH_DIFFUSION_ALLOW_OVERSIZED_LOAD=1, which was not tried.
Verdict
General assessment
The app looks and feels polished: a 24 MB installer, a setup window that shows what it does, a model hub with hardware readout, size warnings and a download timer, and a chat that finds models already on the disk from LM Studio and Ollama. A calculation ran at 11.0 tokens per second on a 27B model. The goal of the test, a picture, was not reached. Picture models were refused because the app counted only 2 GB (before a reboot) and 6 GB (after) as usable against about 17 GB needed; web search and an event search ended in 'Ran out of memory'; and a model start gave no progress for minutes. The tester ran the first tests with many other apps open and did not record the models and settings of some runs.
Fit for the tester's use
Not for this tester on this machine, for now. In his words: 'Everything works, except that the end result is I didn't get it to work.' Chat and model management work on 24 GB; picture generation did not in this test. Training was not tried. The tester plans to look again in three to six months.
ObservedChat works: a 27B 4-bit model from the LM Studio folder answered a calculation at 11.0 tokens per second. Models from Ollama and LM Studio show up in the app.
MeasuredPicture models were refused: flux.2-klein needs about 17 GB; the app counted about 2 GB usable (7 GB free) and, after a reboot, about 6 GB (11 GB free). No picture was produced.
Tester viewA beautiful interface where everything works, but the end result was not reached on a 24 GB Mac.
Scorecard Status: Partial
Installation4/524 MB DMG; setup window with a detail log. No time or disk estimate; four to five minutes (tester estimate). The test started from an existing install.
Onboarding and model choice3/5Picker, hub, hardware readout, size warnings and a download timer are strong. The picker shows parameter counts, not gigabytes; the '7 GB' and '17 GB' messages confused the tester.
Core function2/5Chat answered a calculation. Web page reading and an event search ended in out-of-memory errors; no picture was produced.
Guidance and iteration3/5The refusal message explains the cause and names an override. No progress while a model starts; no explanation of why 7 GB was 'free'.
Performance2/511.0 tok/s on a 27B 4-bit model; out of memory at 34.4k context on a 24 GB Mac, with other apps open.
Documentationn/aNot tested.
Trust and privacyn/aNot audited. The vendor claims 100 percent offline use; web search and downloads need the internet. Offline operation was not tested.
Uninstalln/aNot tested.
Scores are proposals derived from the evidence below (1 = poor, 5 = very good). They are the tester's to confirm. Picture generation, the tester's goal, scores low because no picture was made on this machine.
Test details
App
Unsloth, the desktop app (Unsloth Studio). The notes spell it 'Unsloth', 'Unslothh' and 'Onslaught'; this report uses 'Unsloth'. Observed
Version
Setup log: 'unsloth 2026.8.18 -> 2026.10.3 available, updating'. The version in use after the update is assumed to be 2026.10.3. The window carries the label BETA. The desktop app's own version is not recorded. Assumption
Tester
Hans Kuepper, founder of PromptQuorum
Started
9 October 2026, 1 PM (per the notes). One screenshot shows 5:13 PM, so the test ran for at least four hours. Observed
Ended
Not recorded
Hardware
Mac with 24 GB. The notes say 'macOS M3 24 GB' and later 'M3 24 GB Pro MacBook'. The app's Model hub shows '24 GiB RAM', '0 GiB VRAM + 24 GiB shared' and '12/12 CPU'. The exact chip is not recorded. Observed
System
macOS; version not recorded
Install state
Not a clean install. The setup log says 'Updating existing Unsloth install' and 'existing install detected'; the tester says 'same as before'. Earlier use may explain why models from LM Studio and Ollama were already known. Observed
Download
24 MB DMG (as read by the tester). A dependency step ran on first start (see chapter 1). Observed
Why tested
To see how Unsloth works, 'especially the picture functions'. The tester did not plan to use model optimisation (training).
Objective
Generate pictures locally on the 24 GB Mac. Chat and the model hub were tried on the way. Observed
AI help used
A New York skyline prompt of several hundred words is in the notes; its Markdown bold marks suggest it was AI-written. Not confirmed. The chat model's answers (for example on where it got the model) were not relied on here. Assumption
Every statement carries a label:ObservedMeasuredTester estimateVendor claimThird partyAssumptionTester viewTester errorWhat the labels mean
Disclosure. The tester founded PromptQuorum (promptquorum.com), a content site and directory about local AI apps. Unsloth is listed in that directory and has an existing, separately written review page on the site. The notes record no contact with the vendor, no payment and no sponsorship.
Everything works, except that the end result is I didn't get it to work.
Tester notes, lightly edited from voice transcription.
How the test went
Download, setup and first start
Observed
The installer is a DMG of 24 MB, read by the tester as 'the smallest file I've ever seen'.
Observed
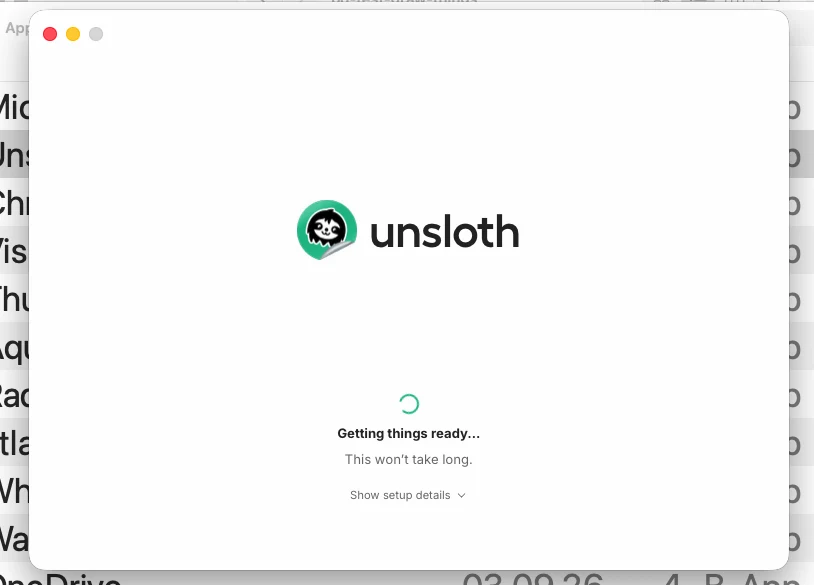
First window: 'Getting things ready... This won't take long.' with a link 'Show setup details'. The tester: 'Already feels much more polished than the other apps... a clear communication.'
Figure 2First window after opening the 24 MB DMG app. The text says it will not take long; the tester measured nothing, and estimates four to five minutes (the update log is in the text). No time or disk estimate is shown.
Observed
The detail log reads: 'Updating existing Unsloth install', 'frontend bundled (Tauri)', 'node v24.13.0 | npm 11.6.2 (system)', 'unsloth 2026.8.18 -> 2026.10.3 available, updating', then a 13-step dependency bar (pip bootstrap, MLX stack for Apple Silicon, base packages, unsloth extras, codecs, overrides, studio deps, data designer, local plugin, diffusers pin, finalizing). Notes: 'torch 2.10.0 detected -- installing torchao==0.16.0'; 'transformers 5.3.0, 5.5.0, 5.10.2 pre-installed'; 'gpu Apple Silicon (Metal, unified memory)'; 'installing prebuilt llama.cpp'.
Observed
The tester says it ran for about four or five minutes, then the app opened. The log shows no time estimate and no disk space estimate.
Tester estimate
Four to five minutes for the setup. Not timed.
Assumption
The small DMG probably downloads most of the software during this first step. Not checked.
Tester view
'It gives me the details about what it does -- great -- but it doesn't tell me anything about estimated time, volumes, how much disk space it takes up.'
Observed
The main window opens with 'How can I help?' and a sidebar: New chat, Model hub, Library, Images, Train, More. The logo carries the label BETA.
Figure 3Main window after the setup. Sidebar: New chat, Model hub, Library, Images, Train, More. The logo carries the label BETA. A browser tab behind the window shows a GitHub page for the project.
Tester error
Started from an existing install ('same as before'), so this is an update, not a first-run test. Onboarding conclusions need a clean install to confirm.
Model picker and the first chat
Observed
The model picker lists Recommended models with figures such as 27.3B and 271.0M. These are parameter counts, not gigabytes. Two entries are greyed out (176.9B and 320.8B).
Figure 4Model picker, Recommended tab. The figures are parameter counts (B = billion, M = million), not gigabytes. Two entries are greyed out (Qwen3.8-Flash-Next-GGUF 176.9B, GLM-5.3-Flash-GGUF 320.8B). What the grey and the yellow dot mean is not stated in the app view captured.
Assumption
Greyed entries are probably too large for this machine. The app view captured does not say so.
Tester view
'There were lots of models listed with the size. Very good.' The numbers shown are parameter counts, so this does not tell the reader how much memory a model needs.
Observed
Instead of choosing a model, the tester typed a request for a calculation. The app started loading models by itself. A Qwen3.8-27B MLX 4-bit model started in under a minute, per the notes; a second toast showed Mistral-7B-Instruct-v0.3-4bit loading (screenshot withheld, same type as Figure 5).
Observed
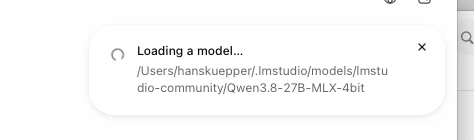
The loading toast shows the path /Users/hanskuepper/.lmstudio/models/lmstudio-community/Qwen3.8-27B-MLX-4bit. The model was read from LM Studio's folder on the disk.
Figure 5Toast shown when the first chat started. The path points into LM Studio's model folder: /Users/hanskuepper/.lmstudio/models/lmstudio-community/Qwen3.8-27B-MLX-4bit. The model was loaded from disk, not downloaded.
Tester view
He suspected it came from the hard drive, because 'that's a big model that doesn't go over the internet in one minute'. The path supports this. Why Unsloth chose this model and the Mistral one is not recorded.
Observed
The question 'what is 5 times 866' was answered '5 x 866 = 4,330' (correct), after 'Worked for 10s', at 11.0 tok/s. The header shows 'Local' and a context meter '120 / 262.1k'.
Figure 6First chat. The answer 4,330 is correct (5 x 866). The screen shows 'Worked for 10s', 11.0 tok/s and a context meter '120 / 262.1k'.
Observed
The tester then asked the model where it got the model from. The captured part of the answer talks about MLX weights and Apple Silicon unified memory; the full answer is not captured. The notes say the answer was that the app does not search the drive.
Assumption
The chat model's own account of the app is not reliable evidence. One answer calls the model 'Qwen 3 27B MLX 4-bit', while the app names it Qwen3.8-27B-MLX-4bit.
Models already on the disk: LM Studio and Ollama
Observed
The On Device tab lists models by source. Under CUSTOM FOLDERS two paths appear (.lmstudio/models and .ollama/models) with Ollama models gemma4:latest, gemma3:1b and qwen3-coder:30b. Under LM STUDIO the Qwen3.8-27B model is marked 'Loaded'.
Figure 7On Device tab. Under CUSTOM FOLDERS two paths are listed (.lmstudio/models and .ollama/models) with Ollama models gemma4:latest, gemma3:1b and qwen3-coder:30b; under LM STUDIO the Qwen3.8-27B model is marked 'Loaded'. A partly visible chat answer behind the list talks about MLX weights. Whether the folders were added by the tester or found automatically is not recorded.
Assumption
Either the tester added the two folders or the app found them on its own. Not recorded. Earlier use of the app may have set them up.
Observed
Switching to qwen3-coder:30b (30.5B, Q4_K_M, GGUF) shows 'Starting model... Switching models. Loading cached model into memory.' with a Cancel button. The context meter reads '1.3k / 8.2k', much smaller than the 262.1k of the first model.
Figure 8Switching to the Ollama model qwen3-coder:30b (30.5B, Q4_K_M, GGUF). Context meter '1.3k / 8.2k'. The toast reads 'Starting model... Switching models. Loading cached model into memory.' with a Cancel button.
Tester view
'I like how easy to change models.' 'Some Ollama models do not work inside Unsloth, but great that it tried at least.'
Observed
Per the notes, an older model worked and a newer one crashed. Which models were meant is not recorded.
Tester view
He says it is 'great that it tried' to use his Ollama models, and that reading models already on the disk avoids another large download.
Model hub and downloads
Observed
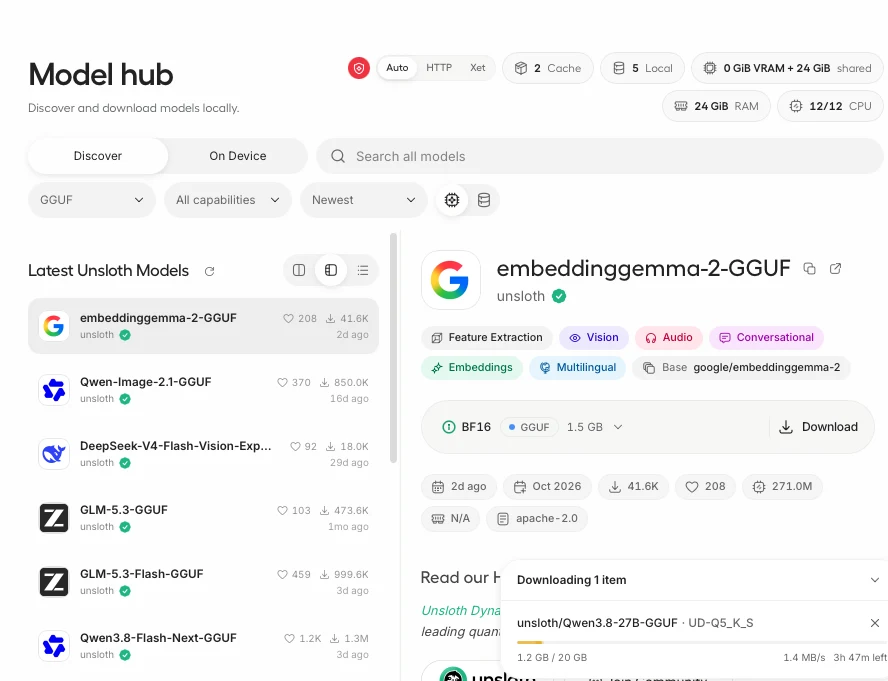
The hub shows the device: '0 GiB VRAM + 24 GiB shared', '24 GiB RAM', '12/12 CPU', plus filters (format, capabilities, newest). Cards show likes, downloads, age and license (embeddinggemma-2-GGUF: apache-2.0, 1.5 GB).
Figure 9Model hub. Top right: '0 GiB VRAM + 24 GiB shared', '24 GiB RAM', '12/12 CPU'. Download panel: unsloth/Qwen3.8-27B-GGUF UD-Q5_K_S, 1.2 GB of 20 GB, 1.4 MB/s, 3 h 47 m left. The open model card, embeddinggemma-2-GGUF (1.5 GB, apache-2.0), is not the downloading model.
Tester view
'Yes, great model hub.' The hub lists, among others, Qwen-Image-2.1-GGUF (850.0K downloads, 16 days old), GLM-5.3-GGUF and Qwen3.8-Flash-Next-GGUF.
Observed
Per the notes, clicking a file that is too big for the Mac gave several warnings ('this file is 30 to 40 gigabytes total'); the download is still allowed. No screenshot.
Measured
The download panel for unsloth/Qwen3.8-27B-GGUF UD-Q5_K_S reads 1.2 GB of 20 GB at 1.4 MB/s, 3 h 47 m left; later 7.1 GB of 20 GB at 983 KB/s, 3 h 31 m left.
Figure 10Same download later: 7.1 GB of 20 GB at 983 KB/s with 3 h 31 m left. The time between this and the previous screenshot is not recorded.
Tester view
'The professionalism of this app is visible. It has a timer attached. It tells you the download speed.'
Assumption
The speeds suggest a slow connection at the test location; the tester does not say so. Whether the download finished is not recorded.
Measured
The Z-Image (BF16) dialog lists model files 12.3 GB plus required encoder and decoder 8.2 GB, total 20.5 GB. This explains the 'difference between the gigabytes that the model has and then something else', which the tester mentions elsewhere.
Figure 19Download dialog for Z-Image (BF16): model files 12.3 GB, 'Include required files' 8.2 GB (encoder and decoder, shared across compatible variants), total 20.5 GB. 'Downloading will not load this model or switch your current model.'
Tester view
The notes say 'the picture LLM was downloaded'. Which one is not recorded; the screenshots show picture models FLUX.2-klein-4B and its GGUF variant on the device (Figure 18).
Web search, voice and the crashes
Observed
The tester pasted a PromptQuorum page URL and asked 'from a seo perspective will this help me?'. The chat shows 'Using tool: Reading promptquorum.com' and 'Waiting for approval: web_search' with the buttons Allow, Always allow and Deny. Timestamp 5:13 PM; context '648 / 34.4k'.
Figure 11Chat with Qwen3.8-27B-MLX-4bit, context '648 / 34.4k', time stamp 5:13 PM. The prompt gives a PromptQuorum URL and asks about SEO. The app shows 'Waiting for approval: web_search' and the buttons Allow, Always allow, Deny. The mode is 'Approve for me'.
Observed
Per the notes, the first try said it could not read the page; after clicking the Search function it worked the second time. 'Maybe the first time should have had a warning.'
Assumption
The first failure may have come from the missing web-search approval or the Search toggle being off. Not verified.
Observed
The run ended with 'Ran out of memory. Try a smaller model or shorter input.' after 168.10 s, with a Retry button.
Figure 12The same chat ends with 'Ran out of memory. Try a smaller model or shorter input.' after 168.10 s.
Observed
Voice input is built in. Using it asks to download the 'Qwen3-ASR 0.6B' speech model, about 1.0 GB, which it says is fetched once into the Hugging Face cache. Whether the tester downloaded it is not recorded.
Figure 13Voice input: 'Local dictation runs entirely offline, but it needs the Qwen3-ASR 0.6B speech model first. About 1.0 GB, fetched once into your Hugging Face cache.' Whether the tester downloaded it is not recorded.
Observed
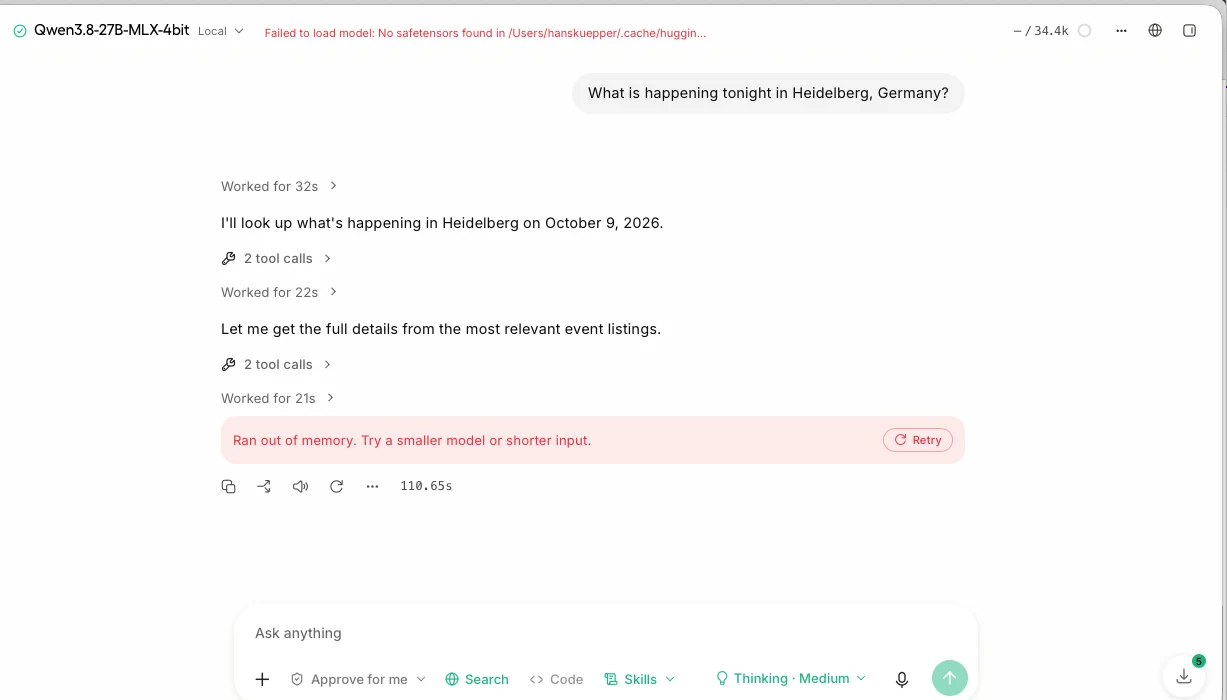
A local event search ('What is happening tonight in Heidelberg, Germany?') ran two rounds of tool calls and ended with 'Ran out of memory' after 110.65 s. The header shows a red note: 'Failed to load model: No safetensors found in /Users/.../.cache/huggin...'.
Figure 14Local event search. Header (red): 'Failed to load model: No safetensors found in /Users/.../.cache/huggin...'. In the chat, two rounds of 'tool calls', then 'Ran out of memory. Try a smaller model or shorter input.' after 110.65 s. Context '- / 34.4k'. The download badge shows 5.
Assumption
The load error and the out-of-memory message may be linked (a model being swapped while memory ran short). The screenshot does not show a link.
Tester view
'But yes, local AI, always some issues.'
Picture models: refused for memory
Observed
The tester's goal was pictures. The sidebar has an 'Images' item. The notes show a long New York skyline prompt (Brooklyn view, Brooklyn Bridge, golden hour, 8K detail) with composition and avoid lists. No result, error or settings are recorded for it.
Measured
Loading the picture model flux.2-klein was refused: 'needs about 17 GB of memory for its weights, but only about 2 GB is usable on this device (of the 7 GB currently free, after reserving room for the operating system)'. It adds that the Mac has one memory pool, offloading to the CPU frees nothing, and suggests a smaller model, a lower quant or closing other apps. It names UNSLOTH_DIFFUSION_ALLOW_OVERSIZED_LOAD=1 as an override.
Figure 1Refusal to load the picture model flux.2-klein. The app reports about 17 GB needed, about 2 GB usable (7 GB currently free, minus room for the operating system). It names an override variable, UNSLOTH_DIFFUSION_ALLOW_OVERSIZED_LOAD=1, which was not tried.
Measured
After a clean reboot the message reads: about 17 GB needed, about 6 GB usable, of 11 GB currently free.
Figure 15Second refusal of flux.2-klein: about 17 GB needed, about 6 GB usable (11 GB currently free). Read here as taken after the clean reboot, per the order in the notes.
Assumption
The two messages differ by 5 GB in both pairs (7 - 2 and 11 - 6), so the app seems to hold back about 5 GB for the operating system. Two data points only.
Observed
The device list shows FLUX.2-klein-4B-GGUF (7.8 GB), FLUX.2-klein-4B (16 GB) and mistral-7b-v0.3-bnb-4bit (4.1 GB). The tester: 'This should be small enough.' The tester says the smallest picture model on the hub crashes his 24 GB machine, and that the models he clicked all said they were too big because only 'seven gigabytes' were available.
Figure 18Models on the device under UNSLOTH: FLUX.2-klein-4B-GGUF (BF16, picture icon, 4B, 7.8 GB), FLUX.2-klein-4B (picture icon, 4B, 16 GB), mistral-7b-v0.3-bnb-4bit (7B, 4.1 GB).
Tester error
The tester wonders why only seven gigabytes are available ('I have much more'). The dialog states that 7 GB were free at that moment and that the other apps were running; after the reboot it states 11 GB. The notes place the '7 GB' remark next to the Z-Image dialog; the 7 GB figure is in the flux.2-klein message.
Tester view
'I'm lost... I have a 24-gigabyte machine and I cannot find an LLM that can serve me and can do the job.' He thinks 24 GB is more than 80 percent of his readers have (his estimate, not a measured figure).
Tester estimate
'More than 80% of my readers' have 24 GB or less. Source not given.
Memory on the Mac
Observed
The tester concludes that local models and daily work compete for the same memory, and that Chrome and other apps take 5 to 8 GB. He wrote 'VRAM' throughout; Apple Silicon has one memory pool, as the hub says ('0 GiB VRAM + 24 GiB shared').
Figure 16Memory panel with a long, flat history. Memory used 12.92 GB, cached files 10.95 GB, app memory 9.81 GB, wired 1.83 GB, swap used 0 bytes. The moment of capture and the apps open are not recorded.
Measured
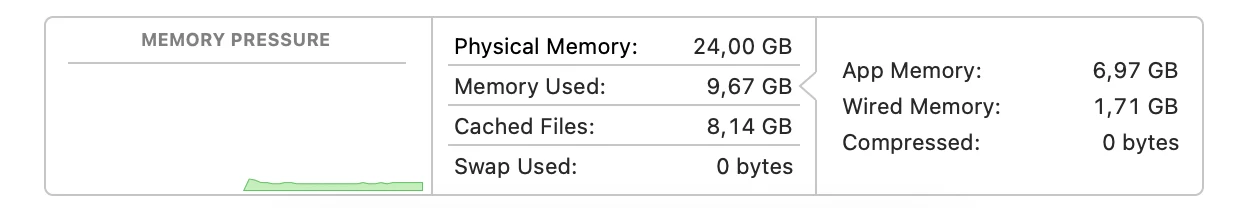
Activity Monitor, another capture: memory used 9.67 GB, cached files 8.14 GB, app memory 6.97 GB, wired 1.71 GB, swap 0. The short history graph fits a recent start.
Figure 17Memory panel with a short history that starts late in the graph. Memory used 9.67 GB, cached files 8.14 GB, app memory 6.97 GB, wired 1.71 GB, swap 0. Matches the '10 GB at startup' remark in the notes; which moment it shows is not recorded.
Assumption
The 11 GB 'currently free' in Figure 15 is consistent with 24.00 - 12.92 = 11.08 GB from Figure 16. That the two were taken at the same time is not recorded.
Tester view
'Even after reboot, already nine gigabytes gone for general things.' 'Either I shut the computer down, reboot, stop all the processes... or I cannot run the LLM.'
Tester view
Two possible answers: models must get smaller and better, or computers need 48 or 64 GB. 'All of this talk about this works on your computer is a little bit fake.'
Assumption
That 48 or 64 GB would 'confidently' fix this is untested.
Loading without feedback, and the closing view
Observed
Starting a model shows a toast 'Starting model... Loading cached model into memory.' with a spinner and Cancel. No percentage, size or time.
Figure 20Model start. The toast shows a spinner and 'Loading cached model into memory.' No percentage, no size, no time. The tester says it ran longer than two or three minutes (estimate).
Tester estimate
The wait ran longer than two or three minutes (not timed).
Tester view
'The worst way you can treat a client is to do the work and not update the client.' The tester names this a user interface issue.
Observed
Header meters show tokens used against the context (for example '648 / 34.4k') and tokens per second (11.0 tok/s).
Tester error
The notes say 'no token counter'. The screenshots show a context meter and a tokens-per-second figure. A per-message token count may be what he meant (assumption).
Tester error
The notes call a local chat model 'the most stupid idea' because it 'does not research the internet'. The same notes and screenshots show a Search function, a web-search approval prompt and tool calls reading a page.
Tester view
He does not want to train models; the chat function is of little use to him; he wants a picture and video tool and 'is not seeing it yet'. Training and the 'Train' tab were not tried.
Tester view
'Maybe it's on my side, but no, not for me. I'll check again in three or six months, but currently not on a M3 24 GB Pro MacBook.'
Claims versus what the tester saw
Claim
Source
Observed
Label
'Run and train image and video diffusion or multimodal models', locally (GitHub README; docs page)
Vendor, read 16 Oct 2026
No picture was made. flux.2-klein was refused (about 17 GB needed; 2 GB and 6 GB usable). Smaller picture variants were not shown to load. Training not tried.
Observed
'Training, MLX and GGUF inference all work inside of Unsloth' on macOS (docs)
Vendor, read 16 Oct 2026
An MLX model (Qwen3.8-27B 4-bit) and a GGUF model (qwen3-coder:30b) loaded and answered. Training not tried.
Observed
'Can be used 100% offline and locally on your computer' (docs)
Vendor, read 16 Oct 2026
Web search and downloads used the internet. Offline use was not tested.
Observed
Web search 'visits pages directly' (docs)
Vendor, read 16 Oct 2026
A page read was attempted; per the notes the first try failed and the second read the page. The run then ran out of memory.
Observed
Desktop app 'free and open source' (release notes)
Vendor, read 16 Oct 2026
No payment prompt appears in the notes or screenshots.
Observed
Hardware shown in the hub
App
The hub showed 24 GiB RAM, 0 GiB VRAM + 24 GiB shared and 12/12 CPU. The RAM figure matches the Mac's 24.00 GB.
Measured
'No hardware requirements stated' (pages read)
Vendor, read 16 Oct 2026
Neither the GitHub page nor the docs page stated a memory requirement in the text returned. The app states its own need at load time (17 GB for flux.2-klein).
Observed
Does it fit in 24 GB?
24 GB memory
flux.2-klein weights, per the refusal messageabout 17 GB needed below 24 GBMeasured
Usable per the app, before the rebootabout 2 GB of 7 GB free below 24 GBMeasured
Usable per the app, after the rebootabout 6 GB of 11 GB free below 24 GBMeasured
Mac memory used, Activity Monitor (first capture)12.92 GB used below 24 GBMeasured
Mac memory used, Activity Monitor (second capture)9.67 GB used below 24 GBMeasured
Z-Image BF16 total download12.3 GB model + 8.2 GB required files (download size) below 24 GBMeasured
Rows 2, 3 and 8 are file or download sizes, not memory use at run time. The 17 GB figure is the app's own estimate for flux.2-klein; which file variant it refers to is not recorded. 'Usable' is the app's figure after reserving room for the operating system. The Qwen3.8-27B MLX 4-bit model ran in chat; its memory use was not read.
Tester errorTested an update of an existing install ('same as before'), not a first-run install.
Tester errorRan the first memory tests with Chrome, the Claude app, Word, WhatsApp and other apps open on a 24 GB Mac. The first refusal showed 7 GB free.
Tester errorUsed 'VRAM' for memory throughout, although the app says '0 GiB VRAM + 24 GiB shared'.
Tester errorWrote that there is 'no token counter'; the screenshots show a context meter and tokens per second.
Tester errorWrote that a local chat model 'does not research the internet'; the screenshots show a Search function and web-search tool calls.
Tester errorRead the model picker's figures as sizes; they are parameter counts.
Tester errorNoted that only seven gigabytes were available without saying what else was open; the dialog says 7 GB were free at that moment.
Tester errorLeft gaps in the record: the desktop app's version, macOS version, the chip, end time, which model was used for the New York prompt and what happened to it, which Ollama models failed, whether the 20 GB download finished, the settings of the picture runs, and uninstall.
Tester errorSpelled the app 'Onslaught' and 'Unslothh' in the notes (voice transcription).
AssumptionThe notes place the Z-Image dialog next to the remark about 'only seven gigabytes'; the 7 GB figure is in the flux.2-klein messages. Screenshots were matched to the text by what they show, not only by their order.
Findings register
ID
Finding
Category
Label
Severity
Figures
UN-01
The DMG is 24 MB, much smaller than the other apps the tester has seen.
The tester judges the interface beautiful and smooth, but could not reach a result and sees no reason to use the app now.
Overall
Tester view
Medium
-
UN-26
Directory lists the license as Apache-2.0; the GitHub page says the Studio UI is AGPL-3.0 and the core Apache-2.0.
Maintenance
Third party
Medium
-
Severity is the impact on a first-time user. Proposed, not measured.
Who it is for
Likely fit
AssumptionUsers with more memory than 24 GB, or a clean machine with few apps open, who want chat, a model hub and local models from LM Studio and Ollama in one app.
Vendor claimPeople who want to train or fine-tune models, which is the project's main purpose per the vendor (not tested here).
Likely poor fit
Tester viewSomeone who wants local picture generation on a 24 GB Mac while other apps are open. It did not work for the tester.
Tester viewSomeone who wants a quick result without learning about models, memory and training.
Retest. The tester plans to check again in three to six months (about January to April 2027). Before then, record the desktop app version, macOS version and chip; start from a clean install; close other apps and note free memory; try a picture model that fits (for example the 7.8 GB GGUF) and record each setting and result; test training, offline use and uninstall.
The worst way you can treat a client is to do the work and not update the client.
Tester notes, lightly edited from voice transcription.
Frequently asked questions
Can Unsloth generate images on a 24 GB Mac?
Not in this test. Loading the picture model flux.2-klein was refused twice: about 17 GB needed, about 2 GB usable (7 GB free) at first, and about 6 GB usable (11 GB free) after a reboot. No picture was produced. Measured
Does Unsloth find models I already have in LM Studio or Ollama?
Yes, in this test. The first chat loaded a Qwen3.8-27B 4-bit model from LM Studio's model folder without a download, and the On Device list showed Ollama models such as gemma4:latest and qwen3-coder:30b. Some Ollama models did not work; which ones is not recorded. Observed
How fast is Unsloth chat on a 24 GB Mac?
A 27B 4-bit model answered 'what is 5 times 866' (4,330, correct) in 10 seconds at 11.0 tokens per second. Reading a web page and an event search with the same model ended in 'Ran out of memory', with other apps open. Measured
How big is the Unsloth installer, and how long does setup take?
The DMG is 24 MB. The first start ran a 13-step dependency update that the tester estimates at four to five minutes; the window shows no time or disk estimate. The test started from an existing install, not a clean one. Observed
Can Unsloth be used fully offline?
The vendor's documentation says it can be used 100 percent offline and locally. Offline use was not tested; web search and model downloads used the internet. Vendor claim
Background on the maker
Not hands-on. The items below come from the vendor's GitHub page, documentation and release page, and the PromptQuorum directory. They were read on 16 October 2026 by a web-fetch tool that summarises pages, and were not independently verified.
Vendor claimThe GitHub page describes Unsloth as the 'first desktop app to run and train models' and 'Local UI to run and train LLMs and diffusion models'. It offers Unsloth Studio (web UI) and Unsloth Core (code). The pages read did not name a company or a person.
Vendor claimLicense: core package Apache 2.0; 'certain optional components, such as the Unsloth Studio UI' are AGPL-3.0.
Vendor claimPlatforms: Windows, Linux, WSL and macOS. Install options: desktop app (a .dmg for macOS), a shell script, Homebrew and Docker. Hardware requirements were not stated in the text returned.
Vendor claimStudio docs: runs GGUF, MLX and diffusion image and video models locally; 'Training, MLX and GGUF inference all work inside of Unsloth' on macOS; web search 'visits pages directly'; 'can be used 100% offline'.
Third partyThe PromptQuorum directory lists Unsloth as free, Apache-2.0, for Mac, Windows and Linux, in the category fine-tuning and LoRA, with about 76,100 GitHub stars (data verified 13 Sep 2026). It records a macOS DMG in release v0.1.905-beta (checked 9 Oct 2026) and a last upstream update on 16 Oct 2026. PromptQuorum has not hands-on tested it before this report.
AssumptionThe release page read on 16 Oct 2026 returned v0.1.806-beta (2 Sep) as the latest, which differs from the directory's v0.1.905-beta; the summarising tool may have read a stale page. The Python package version in the setup log (2026.10.3) is a different numbering from the desktop app's tags.